
How to Clip a NetCDF Grid to a Polygon in Python
On this page
Problem statement
Clipping a climate grid to a country, catchment or region is the first step of most regional analyses, and rioxarray makes it one call. That call decides which cells belong to the polygon by their centres — or, with all_touched=True, by any contact at all — and on a coarse grid that decision is the result. It also fails outright, or silently returns the wrong cells, when the grid's longitude convention, spatial dimensions or CRS are not what it expects.
Measured on the NCEP/NCAR Reanalysis 1 monthly air temperature at 2.5°, averaged over 1991–2020, against Natural Earth 50 m country polygons:
- Belgium contains one cell centre. With
all_touched=Trueit got 5 cells; the polygon's true share of the grid was 0.63 of a cell. all_touched=Trueput the Netherlands in the Caribbean. Its overseas islands touched two tropical cells, and the mean rose from 10.11 °C to 16.57 °C.- Japan's mean was 12.04 °C by centres, 15.48 °C with
all_touchedand 12.73 °C weighted by the share of each cell inside the country. - On the grid left at 0–360 longitude, clipping Brazil raised
NoDataInBounds, and the United States, even withall_touched=True, kept 4 cells out of 274.
Quick answer
Put the grid in the polygons' longitude convention, declare its spatial dimensions and CRS, crop to the bounding box, then clip:
import geopandas as gpd
import rioxarray  # noqa: F401  registers the .rio accessor
import xarray as xr

world = gpd.read_file("ne_50m_admin_0_countries.zip")
country = world[world.ADMIN == "United Kingdom"]

air = xr.open_dataset("air.mon.mean.nc")["air"]
air = air.assign_coords(lon=((air.lon + 180) % 360) - 180).sortby("lon")
air = air.rio.set_spatial_dims(x_dim="lon", y_dim="lat").rio.write_crs("EPSG:4326")
clipped = air.rio.clip_box(*country.total_bounds).rio.clip(country.geometry, country.crs)
print(dict(clipped.sizes), int(clipped.isel(time=0).notnull().sum()), "cells")
{'time': 938, 'lat': 3, 'lon': 3} 6 cells
Then count the cells you kept. If the polygon is small compared with a grid cell, weight cells by the share of their area inside it instead of clipping (Example 2).
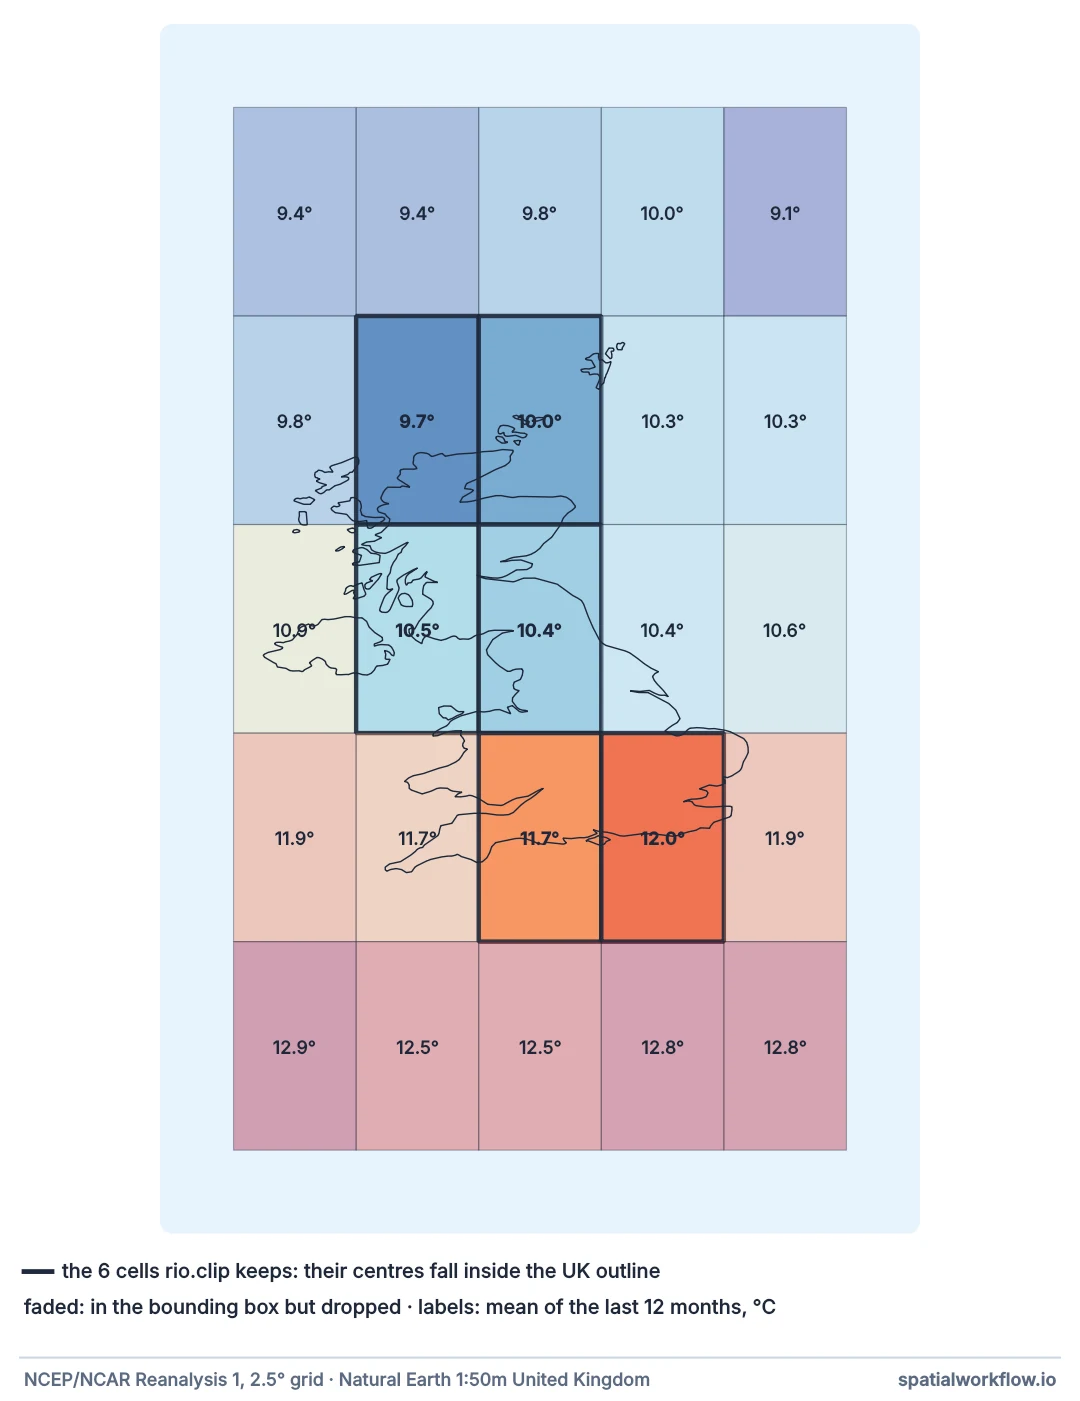
rio.clip, the rest of the bounding box is dropped. Northern Ireland, Wales with the south-west peninsula, and the Hebrides all fall in dropped cells, which is why a country this size needs area-weighted cells rather than a clip.Match longitudes, declare the CRS, crop, then mask
1. Match the longitude convention
Natural Earth polygons, like almost all vector data, use longitudes from −180 to 180; the NCEP grid runs from 0 to 357.5. Clipped without converting, Brazil — entirely at negative longitudes — raised NoDataInBounds: No data found in bounds. The United States raised it too by cell centres, and with all_touched=True returned 4 cells, all at 52.5° N between 172.5° E and 180°: the western Aleutian Islands, the only part of the country with positive longitudes. Converted, the same clip kept 274. Convert with ((lon + 180) % 360) - 180 and sort; the details are in longitude conventions explained.
2. Declare the spatial dimensions and the CRS
rioxarray needs to know which dimensions are x and y and what coordinate system the grid uses. It recognised NCEP's lat and lon from their attributes, but without a CRS the clip raised MissingCRS: CRS not found. Please set the CRS with 'rio.write_crs()'. For OISST, whose coordinates lack the attributes rioxarray looks for, it raised MissingSpatialDimensionError until rio.set_spatial_dims(x_dim="lon", y_dim="lat") was called. Set both explicitly every time.
3. Expect the other dimensions to come along
A clip leaves the non-spatial dimensions alone: the 938-month cube came back as (938, 3, 3) for the United Kingdom, with time intact, and OISST's four-dimensional (time, zlev, lat, lon) clipped as it was, to (1, 1, 11, 7). That OISST clip also shows step 1 again: left at 0–360, it kept only the strip of the UK east of Greenwich.
4. Crop to the bounding box first
rio.clip builds a mask for the whole grid. On the 938-month cube, clipping the United Kingdom took 63.9 ms; cropping to its bounding box with rio.clip_box and then clipping took 9.0 ms (medians of 20 runs, on an idle machine). The saving grows with the grid.
5. Decide what "inside" means
By default a cell is kept when its centre lies inside the polygon; all_touched=True keeps every cell the polygon touches. On a 2.5° grid the difference is large:
country          centre cells  mean     all_touched cells  mean     share-weighted mean  (cells)
Belgium               1       10.72 °C          5         10.50 °C       10.83 °C          0.63
Netherlands           1       10.11 °C          7         16.57 °C       10.11 °C          0.78
Switzerland           1        6.66 °C          6          8.48 °C        6.67 °C          0.78
United Kingdom        6        9.51 °C         17         10.03 °C        9.86 °C          5.30
Japan                 9       12.04 °C         30         15.48 °C       12.73 °C          6.06
Chile                13        8.87 °C         39          8.91 °C        8.45 °C         12.30
The last column is the reference: each cell weighted by the share of its area inside the country and by cos(latitude). Centre cells were closer to it for most countries; all_touched was far off wherever a polygon has small outlying parts.
6. Check what all_touched added
The Netherlands' 7 touched cells included two in the Caribbean — at 17.5° N 62.5° W and 12.5° N 67.5° W, averaging over 26 °C — which its overseas islands covered by 0.04% and 0.29%. Japan's southern islands did the same over open Pacific. Listing the cells a clip keeps, with the share of each inside the polygon, catches this in seconds (Example 3).
7. Weight by cell share when polygons are small
When a polygon covers only a few cells, neither rule is adequate: centre-only can keep nothing, and all-touched counts a sliver as a whole cell. Weighting every cell by the share of its area inside the polygon uses all the information. For a per-polygon time series over many polygons, build those weights once and reuse them, as in extracting a time series per polygon.
8. Weight by area when you average
Clipped cells still have different areas. Average them with cos(latitude) weights — clipped.weighted(np.cos(np.deg2rad(clipped.lat))).mean(("lat", "lon")) — as in taking an area-weighted mean. The rule for which cells count and the rule for how they are weighted are separate decisions.
Clipping reanalysis temperature to country shapes
The data used on this page
The NCEP/NCAR Reanalysis 1 monthly mean air temperature from NOAA PSL (2.5°, from January 1948), the OISST daily sea-surface temperature for 15 January 2024 (0.25°), WorldClim 2.1's 10′ bioclimatic grids (1970–2000) and Natural Earth's 1:50m countries:
import os
import subprocess

PSL = "Datasets/ncep.reanalysis/Monthlies/surface/air.mon.mean.nc"
FILES = {
    "air.mon.mean.nc": [f"https://downloads.psl.noaa.gov/{PSL}", f"https://psl.noaa.gov/thredds/fileServer/{PSL}"],
    "oisst-avhrr-v02r01.20240115.nc": ["https://www.ncei.noaa.gov/data/sea-surface-temperature-optimum-interpolation/"
                                       "v2.1/access/avhrr/202401/oisst-avhrr-v02r01.20240115.nc"],
    "ne_50m_admin_0_countries.zip": ["https://naciscdn.org/naturalearth/50m/cultural/ne_50m_admin_0_countries.zip"],
    "wc2.1_10m_bio.zip": ["https://geodata.ucdavis.edu/climate/worldclim/2_1/base/wc2.1_10m_bio.zip"],
}
for name, urls in FILES.items():
    for url in urls * 5:                                 # PSL drops connections: resume and retry
        if os.path.exists(name):
            break
        if subprocess.run(["curl", "-sfL", "-C", "-", "--retry", "3", "-o", name + ".part", url]).returncode == 0:
            os.replace(name + ".part", name)
    if not os.path.exists(name):
        raise RuntimeError(f"could not download {name}")
print({name: os.path.getsize(name) for name in FILES})
{'air.mon.mean.nc': 29583703, 'oisst-avhrr-v02r01.20240115.nc': 1545085, 'ne_50m_admin_0_countries.zip': 799734, 'wc2.1_10m_bio.zip': 49869449}
Example 1 — a clip that fixes the usual obstacles and reports its cells
import geopandas as gpd
import numpy as np
import rioxarray  # noqa: F401
import xarray as xr


def clip_to_polygons(da, polygons, all_touched=False, x="lon", y="lat"):
    """Clip a latitude-longitude DataArray to polygons; return the clip and the number of cells kept."""
    if float(da[x].max()) > 180:
        da = da.assign_coords({x: ((da[x] + 180) % 360) - 180}).sortby(x)
    da = da.rio.set_spatial_dims(x_dim=x, y_dim=y).rio.write_crs("EPSG:4326")
    polygons = polygons.to_crs("EPSG:4326")
    box = da.rio.clip_box(*polygons.total_bounds, auto_expand=True)
    clipped = box.rio.clip(polygons.geometry, polygons.crs, all_touched=all_touched)
    first = clipped.isel({d: 0 for d in clipped.dims if d not in (x, y)})
    return clipped, int(first.notnull().sum())


def area_mean(da, x="lon", y="lat"):
    return da.weighted(np.cos(np.deg2rad(da[y]))).mean((y, x))


world = gpd.read_file("ne_50m_admin_0_countries.zip")
climate = xr.open_dataset("air.mon.mean.nc")["air"].sel(time=slice("1991", "2020")).mean("time")
for name in ["United Kingdom", "Belgium", "Japan"]:
    country = world[world.ADMIN == name]
    for touched in (False, True):
        clipped, cells = clip_to_polygons(climate, country, all_touched=touched)
        print(f"{name:15} all_touched={touched!s:5} {cells:3d} cells, mean {float(area_mean(clipped)):.2f} °C")
United Kingdom all_touched=False 6 cells, mean 9.51 °C
United Kingdom all_touched=True 17 cells, mean 10.03 °C
Belgium all_touched=False 1 cells, mean 10.72 °C
Belgium all_touched=True 5 cells, mean 10.50 °C
Japan all_touched=False 9 cells, mean 12.04 °C
Japan all_touched=True 30 cells, mean 15.48 °C
auto_expand=True lets the bounding-box crop grow when a polygon is narrower than a grid cell, instead of raising an error for a one-cell-wide result.
Example 2 — weight cells by the share inside the polygon
import shapely


def share_weighted_mean(da, polygons, x="lon", y="lat"):
    """Mean of a 2-D grid, weighting each cell by its share inside the polygons and by cos(latitude)."""
    geom = shapely.union_all(polygons.to_crs("EPSG:4326").geometry.values)
    dx = abs(float(da[x][1] - da[x][0])) / 2
    dy = abs(float(da[y][1] - da[y][0])) / 2
    lon2, lat2 = np.meshgrid(da[x].values, da[y].values)
    boxes = shapely.box(lon2 - dx, lat2 - dy, lon2 + dx, lat2 + dy)
    share = shapely.area(shapely.intersection(boxes, geom)) / (4 * dx * dy)
    weights = share * np.cos(np.deg2rad(lat2))
    ok = (weights > 0) & np.isfinite(da.values)
    return float((da.values[ok] * weights[ok]).sum() / weights[ok].sum()), float(share.sum())


climate180 = climate.assign_coords(lon=((climate.lon + 180) % 360) - 180).sortby("lon")
for name in ["Belgium", "Netherlands", "Switzerland", "United Kingdom", "Japan", "Chile"]:
    country = world[world.ADMIN == name]
    reference, cells = share_weighted_mean(climate180, country)
    centre, n_centre = clip_to_polygons(climate, country)
    touched, n_touched = clip_to_polygons(climate, country, all_touched=True)
    print(f"{name:14} centre {n_centre:2d} cells {float(area_mean(centre)):6.2f} | "
          f"all_touched {n_touched:2d} cells {float(area_mean(touched)):6.2f} | "
          f"share-weighted {reference:6.2f} ({cells:.2f} cells)")
Belgium centre 1 cells 10.72 | all_touched 5 cells 10.50 | share-weighted 10.83 (0.63 cells)
Netherlands centre 1 cells 10.11 | all_touched 7 cells 16.57 | share-weighted 10.11 (0.78 cells)
Switzerland centre 1 cells 6.66 | all_touched 6 cells 8.48 | share-weighted 6.67 (0.78 cells)
United Kingdom centre 6 cells 9.51 | all_touched 17 cells 10.03 | share-weighted 9.86 (5.30 cells)
Japan centre 9 cells 12.04 | all_touched 30 cells 15.48 | share-weighted 12.73 (6.06 cells)
Chile centre 13 cells 8.87 | all_touched 39 cells 8.91 | share-weighted 8.45 (12.30 cells)
Cell shares are computed in degrees, which is right for a regular latitude–longitude grid: the cos(latitude) weight supplies the change in area with latitude.
Example 3 — list the cells that are barely inside
def barely_inside(da, polygons, threshold=0.05, x="lon", y="lat"):
    clipped, _ = clip_to_polygons(da, polygons, all_touched=True, x=x, y=y)
    geom = shapely.union_all(polygons.to_crs("EPSG:4326").geometry.values)
    half = abs(float(da[y][1] - da[y][0])) / 2
    cells = clipped.stack(cell=(y, x)).dropna("cell")
    for lat, lon, value in zip(cells[y].values, cells[x].values, cells.values):
        cell = shapely.box(lon - half, lat - half, lon + half, lat + half)
        share = shapely.area(shapely.intersection(cell, geom)) / (2 * half) ** 2
        if share < threshold:
            print(f"cell ({lat:5.1f}, {lon:6.1f})  {value:6.2f} °C  {share:.2%} inside")


barely_inside(climate, world[world.ADMIN == "Netherlands"])
cell ( 52.5, 2.5) 10.65 °C 1.33% inside
cell ( 50.0, 2.5) 11.50 °C 0.01% inside
cell ( 50.0, 5.0) 10.72 °C 2.50% inside
cell ( 17.5, -62.5) 26.21 °C 0.04% inside
cell ( 12.5, -67.5) 26.47 °C 0.29% inside
Three slivers along the Dutch border and two Caribbean cells were each less than 3% inside the country.
The function assumes square cells, as on the 2.5° grid here.
Example 4 — the obstacles, reproduced
Each failure the step-by-step section describes, run on the files above. WorldClim's 10′ annual mean temperature stands in for a fine land grid; OISST is sea-surface temperature, so it has no values over land at all.
import time
import zipfile

from rioxarray.exceptions import MissingCRS, MissingSpatialDimensionError, NoDataInBounds


def attempt(label, fn):
    try:
        print(f"{label:34} {fn()}")
    except (MissingCRS, MissingSpatialDimensionError, NoDataInBounds, ValueError) as err:
        print(f"{label:34} {type(err).__name__}: {str(err).split('.')[0]}")


def cells(da):
    return f"{int(da.notnull().sum())} cells"


def ms(fn, repeat=20):
    fn()
    runs = []
    for _ in range(repeat):
        start = time.perf_counter()
        fn()
        runs.append(time.perf_counter() - start)
    return f"{np.median(runs) * 1000:.1f} ms"


raw = xr.open_dataset("air.mon.mean.nc")["air"]
brazil, usa, uk = (world[world.ADMIN == n] for n in ["Brazil", "United States of America", "United Kingdom"])
attempt("no CRS written", lambda: raw.rio.clip(uk.geometry, uk.crs))
grid360 = raw.isel(time=0).rio.write_crs("EPSG:4326")
attempt("0-360 grid, Brazil", lambda: cells(grid360.rio.clip(brazil.geometry, brazil.crs)))
attempt("0-360 grid, USA, all_touched", lambda: cells(grid360.rio.clip(usa.geometry, usa.crs, all_touched=True)))
grid = grid360.assign_coords(lon=((grid360.lon + 180) % 360) - 180).sortby("lon").rio.write_crs("EPSG:4326")
attempt("-180-180 grid, USA, all_touched", lambda: cells(grid.rio.clip(usa.geometry, usa.crs, all_touched=True)))

bng = uk.to_crs("EPSG:27700")
attempt("UK in EPSG:27700, GeoSeries", lambda: cells(grid.rio.clip(bng.geometry, bng.crs, all_touched=True)))
attempt("UK in EPSG:27700, list of shapes", lambda: cells(grid.rio.clip(list(bng.geometry), bng.crs, all_touched=True)))
attempt("UK in EPSG:27700, CRS not passed", lambda: cells(grid.rio.clip(list(bng.geometry), all_touched=True)))

sst = xr.open_dataset("oisst-avhrr-v02r01.20240115.nc")["sst"]
attempt("OISST, dims not set", lambda: sst.rio.write_crs("EPSG:4326").rio.clip(uk.geometry, uk.crs))
sst4 = sst.rio.set_spatial_dims(x_dim="lon", y_dim="lat").rio.write_crs("EPSG:4326")
attempt("OISST (time, zlev, lat, lon)", lambda: dict(sst4.rio.clip(uk.geometry, uk.crs).sizes))
no CRS written MissingCRS: CRS not found
0-360 grid, Brazil NoDataInBounds: No data found in bounds
0-360 grid, USA, all_touched 4 cells
-180-180 grid, USA, all_touched 274 cells
UK in EPSG:27700, GeoSeries ValueError: Unsupported geometry type FeatureCollection
UK in EPSG:27700, list of shapes 17 cells
UK in EPSG:27700, CRS not passed NoDataInBounds: No data found in bounds
OISST, dims not set MissingSpatialDimensionError: y dimension not found
OISST (time, zlev, lat, lon) {'time': 1, 'zlev': 1, 'lat': 11, 'lon': 7}
The three ways of clipping the whole 938-month cube, timed:
cube = raw.assign_coords(lon=((raw.lon + 180) % 360) - 180).sortby("lon").rio.write_crs("EPSG:4326")
attempt("clip whole cube", lambda: ms(lambda: cube.rio.clip(uk.geometry, uk.crs)))
attempt("clip_box, then clip", lambda: ms(lambda: cube.rio.clip_box(*uk.total_bounds).rio.clip(uk.geometry, uk.crs)))
inside = shapely.contains_xy(shapely.union_all(uk.geometry.values), *np.meshgrid(cube.lon, cube.lat))
attempt("shapely.contains_xy mask", lambda: ms(lambda: cube.where(inside)))
clip whole cube 63.9 ms
clip_box, then clip 9.0 ms
shapely.contains_xy mask 59.3 ms
The mask and the clip give the same regional series, and the cell counts depend on resolution:
same = np.allclose(area_mean(cube.where(inside)), area_mean(cube.rio.clip(uk.geometry, uk.crs)))
attempt("  same series as rio.clip", lambda: same)

with zipfile.ZipFile("wc2.1_10m_bio.zip") as z:
    z.extract("wc2.1_10m_bio_1.tif")
fine = rioxarray.open_rasterio("wc2.1_10m_bio_1.tif", masked=True).squeeze("band", drop=True)
coarse = climate.assign_coords(lon=((climate.lon + 180) % 360) - 180).sortby("lon")
for name in ["Belgium", "United Kingdom", "Japan"]:
    country = world[world.ADMIN == name]
    for label, da, x, y in [("2.5°", coarse, "lon", "lat"), ("10′", fine, "x", "y")]:
        n_centre = clip_to_polygons(da, country, x=x, y=y)[1]
        n_touched = clip_to_polygons(da, country, all_touched=True, x=x, y=y)[1]
        print(f"{name:14} {label:4} centre {n_centre:4d}  all_touched {n_touched:4d}  ratio {n_touched / max(n_centre, 1):.2f}")
same series as rio.clip True
Belgium 2.5° centre 1 all_touched 5 ratio 5.00
Belgium 10′ centre 141 all_touched 181 ratio 1.28
United Kingdom 2.5° centre 6 all_touched 17 ratio 2.83
United Kingdom 10′ centre 1188 all_touched 1506 ratio 1.27
Japan 2.5° centre 9 all_touched 30 ratio 3.33
Japan 10′ centre 1365 all_touched 1773 ratio 1.30
Cell centres, all_touched and resolution
Why the cell-centre rule is the default
rioxarray rasterises the polygons onto the grid with GDAL's rules: a cell is inside when its centre is. That matches how most raster tools behave and never counts a cell twice when adjacent polygons are clipped separately. Its weakness is resolution: a polygon smaller than a cell may contain no centre, and a polygon a few cells across keeps or loses whole cells on a coin toss of where its edge falls.
Why all_touched is worse more often than it looks
all_touched=True fixes the empty result for small polygons by keeping every cell that any part of the polygon reaches. Real boundaries are ragged — coastlines, islands, enclaves, overseas territories — so a country touches many cells it barely overlaps, and each of them counts as fully as a cell in its interior. On a 2.5° grid the touched set was 2.8 (United Kingdom) to 7 (the Netherlands) times the centre set for the countries tested.
Why resolution changes the choice
On WorldClim's 10′ grid (about 0.17°) Belgium kept 141 centre cells and 181 touched cells — 1.28 times as many, against 5 times at 2.5°; the United Kingdom and Japan came to 1.27 and 1.30 (Example 4). As cells shrink relative to the polygon, the edge cells become a small share of the total and both rules converge on the share-weighted answer. On fine grids the default is fine; on coarse ones, weight by share.
Why CRS and dimensions must be declared
A NetCDF file has no GDAL-style geotransform or CRS. rioxarray infers the transform from the coordinate values once it knows which dimensions are spatial, and it needs a CRS to reproject polygons onto the grid. Polygons in another CRS work when their CRS is passed: the United Kingdom in British National Grid clipped to 17 cells with all_touched=True when the CRS was given, and raised NoDataInBounds when it was not. Pass the shapes as a list there — the GeoSeries itself raised ValueError: Unsupported geometry type FeatureCollection once it was in a projected CRS, while the same GeoSeries in EPSG:4326 clipped fine.
Small polygons, multipart countries and curvilinear grids
- Polygons with no cell centre clip to an all-NaN array rather than raising; count the cells.
- Multipart countries clip every part, including distant islands.
- Clipping does not reduce memory much on its own unless you crop to the bounding box first.
- A mask with
shapely.contains_xygave an identical series torio.clip, needs no CRS handling for lat/lon polygons, and took 59.3 ms on the full cube — about as long as an uncropped clip, so crop first either way. - Curvilinear model grids cannot be clipped this way; use cell-centre masks on the 2-D coordinates or regrid first.
- Regridding before clipping changes the answer again; see regridding explained.
- Writing the clip to GeoTIFF needs the spatial dims and CRS set as above; see converting NetCDF to GeoTIFF.
Internal links
- How to extract a time series per polygon from a NetCDF grid — many polygons with coverage weights
- 0–360 or −180–180: longitude conventions in gridded data explained — the first obstacle
- How to take an area-weighted mean over a latitude–longitude grid — averaging the clipped cells
- How to clip a raster to a polygon in Python — the GeoTIFF equivalent
- How to convert NetCDF to GeoTIFF in Python — exporting the result
- CF conventions explained: how a NetCDF file says what its numbers mean — why axes are not always detected
- How to select a time range and location from an xarray Dataset — rectangular selections
- Regridding explained: bilinear, conservative and nearest for gridded data — changing resolution first
FAQ
How do I clip a NetCDF file to a shapefile in Python?
Open it with xarray, convert longitude to −180–180 if needed, call rio.set_spatial_dims and rio.write_crs, crop with rio.clip_box and clip with rio.clip using the polygons and their CRS.
Why does rioxarray clip raise NoDataInBounds?
Usually because the grid uses 0–360 longitude and the polygon has negative longitudes, or because the polygons' CRS was not passed. Clipping Brazil on the unconverted NCEP grid raised it.
Should I use all_touched when clipping climate data?
Rarely on coarse grids. It gave the Netherlands two Caribbean cells and a mean of 16.57 °C instead of about 10.1 °C; weight cells by their share inside the polygon instead.
What if my polygon is smaller than a grid cell?
A centre-only clip may keep nothing. Weight the cells by the share of each inside the polygon; Belgium covered 0.63 of a 2.5° cell in total.
Why does rioxarray say it cannot find the x or y dimension?
The coordinates lack the attributes it uses to recognise them. Call rio.set_spatial_dims(x_dim="lon", y_dim="lat") before clipping.
Does clipping keep the time dimension?
Yes. Clipping the 938-month cube to the United Kingdom returned a 938 × 3 × 3 array with the time coordinate intact.