
Fixing Census Totals That Do Not Add Up After Aggregation
On this page
Problem statement
Census data is supposed to be additive: blocks into tracts, tracts into counties, counties into states. Then a check fails.
B01003_E001: 2 of 3,222 parents differ; {'36103': -79296, '36111': -3904}
Or a spatial join of Delaware's census blocks to its tracts reports 1,584,738 people in a state of 989,948. Or an areal interpolation onto a grid quietly loses 10,677 people. Or five sources give five populations for the same state in the same decade.
Each of these has a different cause, and only some of them are errors. Measured on the 2023 ACS 5-year tables and Delaware's 2020 census blocks, the causes fall into five groups: rows missing from one of the tables, geometry joins that count people twice or not at all, interpolation onto zones that do not cover the source, totals from different products, and statistics that were never additive in the first place.
Quick answer
Work out which kind of mismatch you have before changing anything:
bad = additivity(tracts, counties, key_len=5, column="B01003_E001")          # Example 1
joined = assign_blocks(blocks, tracts, "POP20", "representative point")      # Example 2
Then apply the matching fix:
- Children missing from the table — find them in the geography list and report the gap; do not rescale.
- Double counting in a spatial join — assign each small unit by a single point that lies inside it.
- Losses in interpolation — pass
allocate_total=Truewhen the target zones cover the source. - Different products — compare totals only within one product and one vintage.
- Rates, medians and margins — rebuild them from additive counts instead of summing them.
Decide what should add, check by identifier, assign by point
1. Decide what should add up
Counts add up exactly only within a single product, a single vintage and a nesting hierarchy. ACS tract populations should sum to ACS county populations; they are not expected to sum to decennial census counts, to population estimates, or to a county of a different year. Write down the product, year and geography of both sides before testing.
2. Check additivity by identifier
Group the children by the prefix that names their parent and compare with the published parent:
B01003_E001: 2 of 3,222 parents differ; {'36103': -79296, '36111': -3904}
The same check at state level found no mismatches. The two counties are Suffolk and Ulster in New York, and the cause is not arithmetic: 14 Suffolk tracts and one Ulster tract are listed in the ACS geography file and published with no row in the tract table. The children are missing, so the sum is short by exactly their population. Report the gap; rescaling the remaining tracts to the county total would invent numbers for tracts that have none.
3. Assign small units to zones by a point, not by overlap
A spatial join between polygons counts a block once for every zone it touches. Delaware's 20,198 blocks against its 262 tracts:
intersects              28,647 rows  total 1,584,738  (+60.08%)
within                  15,561 rows  total 652,725  (-34.06%)
representative point    20,198 rows  total 989,948  (+0.00%)
intersects matches blocks to neighbouring tracts along shared edges, because boundaries that coincide still count as touching. within rejects every block whose digitised edge wanders a fraction of a metre outside its tract. A representative point is guaranteed to be inside its block, so each block joins exactly one tract. The intersects count is not even stable: the same join run in the files' own NAD83 coordinates, rather than EPSG:5070, returns 28,567 rows instead of 28,647, because which shared edges count as touching depends on how the vertices round in each CRS.
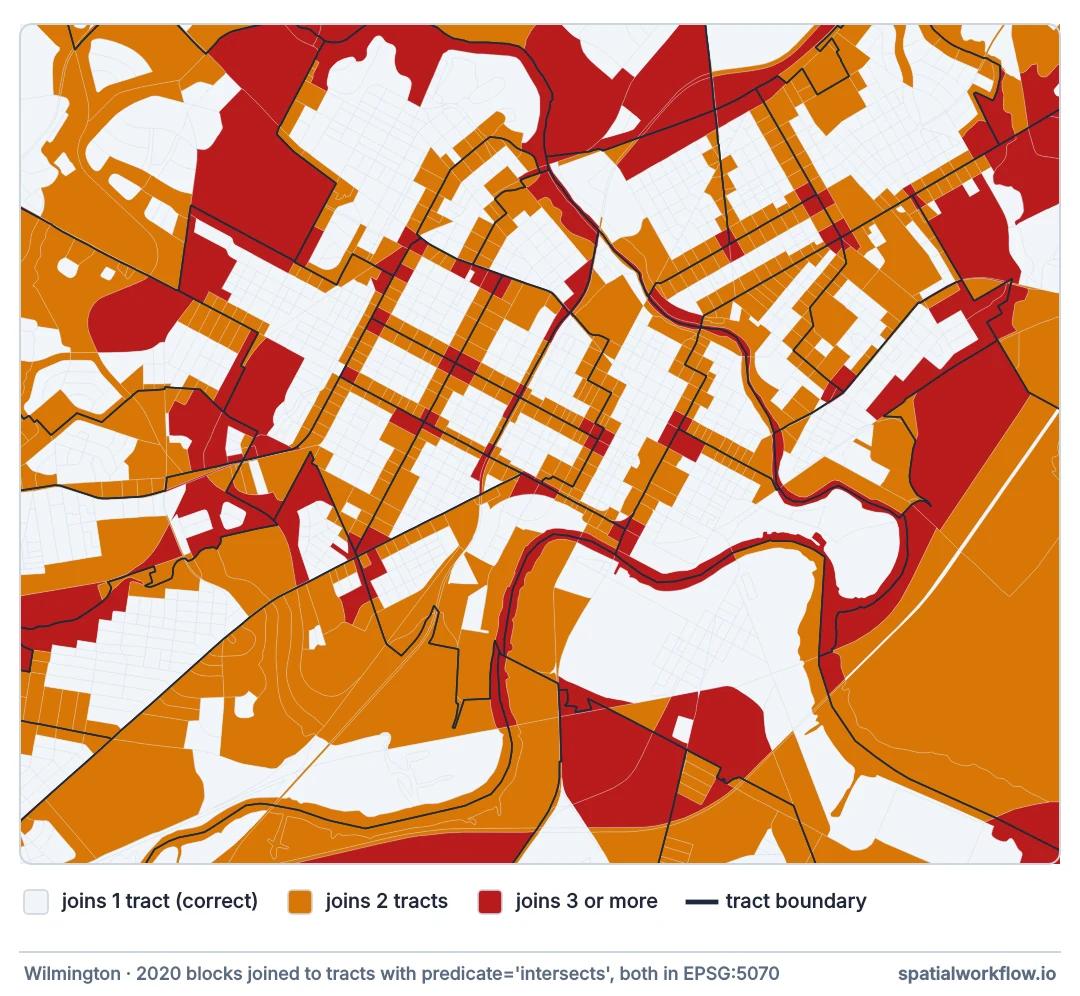
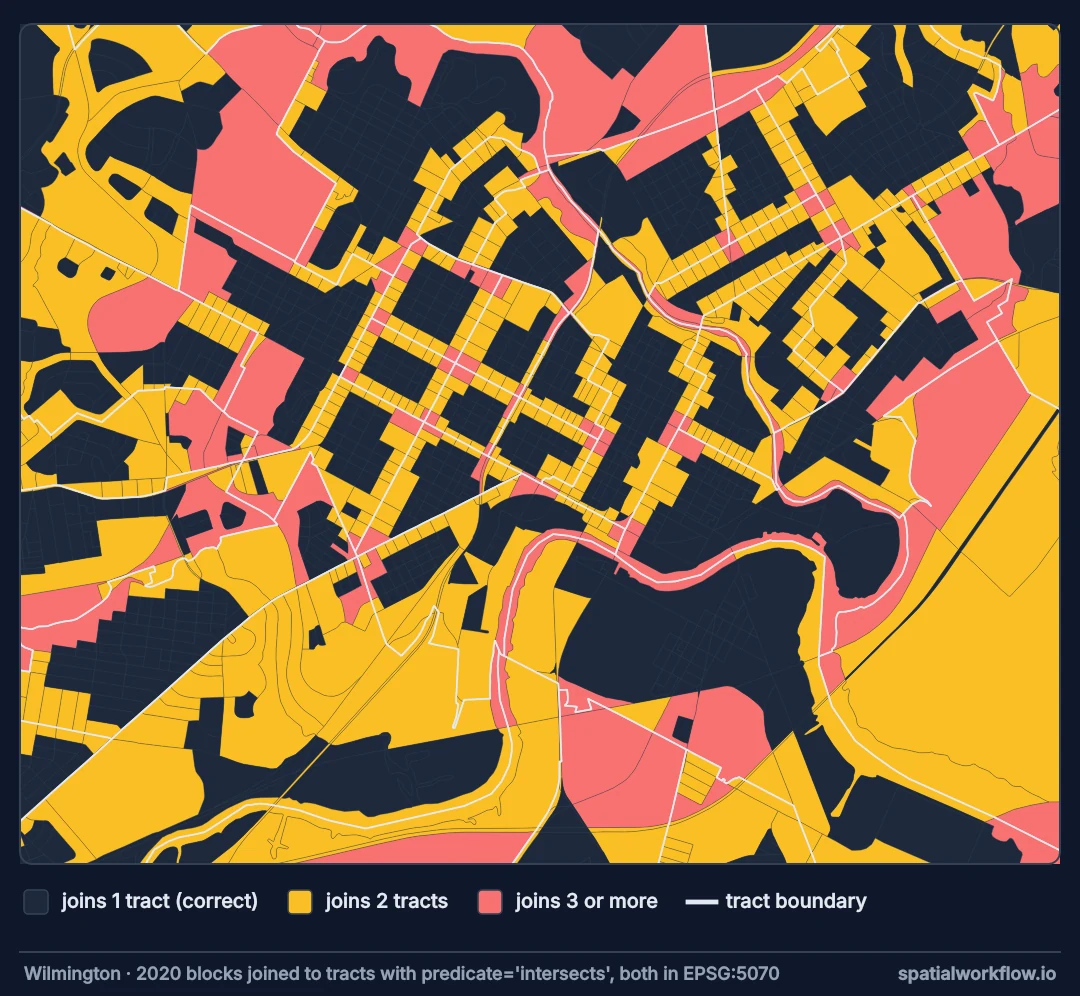
intersects matches it twice (orange), and blocks at corners three or more times (red). Only the blocks in the middle of each tract join once. The boundaries run along streets and rivers, so the double-counted blocks trace the street grid.4. Allocate the whole total when target zones cover the source
Area-weighted interpolation can lose people when target zones do not cover every part of the source zones. Interpolating Delaware's tract populations onto a 2 km grid clipped to the state outline:
allocate_total=True:  total 989,948 of 989,948 (-0.00%)
allocate_total=False: total 979,271 of 989,948 (-1.08%)
The tract polygons include water beyond the generalised state outline — 6,446 km² of tracts against 5,325 km² inside the outline — so area weights leave part of each coastal tract's people in cells that no longer exist. allocate_total=True in tobler normalises each source zone's weights over the targets it actually reaches. Use it when the targets are meant to cover the source; leave it off when a missing share is a real result, such as the population outside a flood zone.
5. Compare totals within one product
Five official figures for Delaware around the start of the decade, the population estimates taken from Vintage 2024:
2020 census blocks                  989,948
estimates base, April 2020          989,955
population estimate, July 2020      991,928
ACS 5-year, 2019–2023             1,005,872
population estimate, July 2023    1,036,423
None of these is wrong. They measure different dates and are produced by different methods: a count, an adjusted base, a model and a survey average over five years. A table that mixes them will never balance, and should not be forced to.
6. Rebuild non-additive statistics from counts
Rates, medians and margins of error do not sum or average into their parents:
- Rates. Delaware's poverty rate from summed counts is 10.73%. The unweighted mean of its tract rates is 11.2%, and their median 8.56%.
- Medians. New Castle County's published median household income is 89,901. The mean of its tract medians is 92,705, and a population-weighted mean is 96,812.
- Margins of error. The county's tract population margins sum to 85,143 and combine by root sum of squares to 7,692; the published county margin is −555555555, because the county total is controlled.
Sum the numerators and denominators, then divide. For medians, aggregate the distribution table and interpolate.
7. Expect overlays not to cover the hierarchy
Places, ZIP Code Tabulation Areas and districts are not built to tile a state. Delaware's 79 places held 435,168 of its 1,005,872 ACS residents, 43.3%. A sum over places is a sum over the people who live in places.
8. Check the geographic extent of "national"
The 50 states and the District of Columbia sum exactly to the published national ACS population of 332,387,540. Adding Puerto Rico gives 335,642,425. A national total that is 3.3 million too high usually includes Puerto Rico on one side only.
Finding parents whose children do not add up
The data used on this page
Delaware, from the Census Bureau: the ACS 2019–2023 5-year table B01003 (total population) from the table-based summary file, which covers every geography in the country in one pipe-delimited file; the 2020 TIGER/Line blocks, which carry the 2020 Census count POP20, and tracts; and the 2023 cartographic boundary file of states at 1:20 million.
import os

import requests

ACS = "https://www2.census.gov/programs-surveys/acs/summary_file/2023/table-based-SF"
FILES = {
    "acsdt5y2023-b01003.dat": "https://www2.census.gov/programs-surveys/acs/summary_file/2023/table-based-SF/data/5YRData/acsdt5y2023-b01003.dat",
    "tl_2020_10_tabblock20.zip": "https://www2.census.gov/geo/tiger/TIGER2020/TABBLOCK20/tl_2020_10_tabblock20.zip",
    "tl_2020_10_tract.zip": "https://www2.census.gov/geo/tiger/TIGER2020/TRACT/tl_2020_10_tract.zip",
    "cb_2023_us_state_20m.zip": "https://www2.census.gov/geo/tiger/GENZ2023/shp/cb_2023_us_state_20m.zip",
    "acsdt5y2023-b17001.dat": f"{ACS}/data/5YRData/acsdt5y2023-b17001.dat",
    "acsdt5y2023-b19013.dat": f"{ACS}/data/5YRData/acsdt5y2023-b19013.dat",
    "Geos20235YR.txt": f"{ACS}/documentation/Geos20235YR.txt",
    "NST-EST2024-ALLDATA.csv": "https://www2.census.gov/programs-surveys/popest/datasets/2020-2024/state/totals/NST-EST2024-ALLDATA.csv",
}
for name, url in FILES.items():
    if not os.path.exists(name):
        r = requests.get(url, timeout=600)
        r.raise_for_status()
        open(name, "wb").write(r.content)
print({name: f"{os.path.getsize(name) / 1e6:.1f} MB" for name in FILES})
{'acsdt5y2023-b01003.dat': '18.3 MB', 'tl_2020_10_tabblock20.zip': '21.5 MB', 'tl_2020_10_tract.zip': '1.1 MB', 'cb_2023_us_state_20m.zip': '0.2 MB', 'acsdt5y2023-b17001.dat': '118.4 MB', 'acsdt5y2023-b19013.dat': '17.9 MB', 'Geos20235YR.txt': '91.9 MB', 'NST-EST2024-ALLDATA.csv': '0.0 MB'}
Example 1 — find the parents whose children do not add up
import pandas as pd


def load_level(path, prefix, cols):
    t = pd.read_csv(path, sep="|", dtype={"GEO_ID": str}, usecols=["GEO_ID"] + cols)
    t = t[t.GEO_ID.str.startswith(prefix)].copy()
    return t.set_index(t.GEO_ID.str[len(prefix):]).drop(columns="GEO_ID")


def additivity(children, parents, key_len, column):
    """Parents whose children do not sum to the published parent value."""
    sums = children[column].groupby(children.index.str[:key_len]).sum()
    diff = (sums.reindex(parents.index) - parents[column]).dropna()
    bad = diff[diff != 0]
    print(f"{column}: {len(bad)} of {len(parents):,} parents differ; {bad.to_dict()}")
    return bad
pop = "B01003_E001"
tracts = load_level("acsdt5y2023-b01003.dat", "1400000US", [pop])
counties = load_level("acsdt5y2023-b01003.dat", "0500000US", [pop])
additivity(tracts, counties, 5, pop)
additivity(counties, load_level("acsdt5y2023-b01003.dat", "0400000US", [pop]), 2, pop)
geos = pd.read_csv("Geos20235YR.txt", sep="|", dtype=str, usecols=["GEO_ID"]).GEO_ID
listed = geos[geos.str.startswith("1400000US")]
missing = listed[~listed.str[9:].isin(tracts.index)]
print(len(missing), "tracts in the geography file with no row in the table:",
missing.str[9:14].value_counts().to_dict())B01003_E001: 2 of 3,222 parents differ; {'36103': -79296, '36111': -3904}
B01003_E001: 0 of 52 parents differ; {}
15 tracts in the geography file with no row in the table: {'36103': 14, '36111': 1}
A non-zero difference names the parent; comparing that parent's children with the geography file names the missing rows. Run it on counts only — the check is meaningless for medians and rates.
Example 2 — the same join three ways
import geopandas as gpd


def assign_blocks(blocks, zones, value, method):
    """Total of `value` after assigning blocks to zones three different ways."""
    if method == "representative point":
        pts = blocks.copy()
        pts["geometry"] = blocks.representative_point()
        joined = gpd.sjoin(pts, zones, predicate="within")
    else:
        joined = gpd.sjoin(blocks, zones, predicate=method)
    total = joined[value].sum()
    print(f"{method:22} {len(joined):6,} rows  total {total:,}  ({total / blocks[value].sum() - 1:+.2%})")
    return joined
blocks = gpd.read_file("tl_2020_10_tabblock20.zip", columns=["GEOID20", "POP20"]).to_crs(5070)
tracts = gpd.read_file("tl_2020_10_tract.zip", columns=["GEOID"]).to_crs(5070)
for method in ("intersects", "within", "representative point"):
assign_blocks(blocks, tracts, "POP20", method)
raw_blocks = gpd.read_file("tl_2020_10_tabblock20.zip", columns=["GEOID20"]) # NAD83, as published
raw_tracts = gpd.read_file("tl_2020_10_tract.zip", columns=["GEOID"])
print(f"intersects in {raw_blocks.crs.name}: "
f"{len(gpd.sjoin(raw_blocks, raw_tracts, predicate='intersects')):,} rows")intersects 28,647 rows total 1,584,738 (+60.08%)
within 15,561 rows total 652,725 (-34.06%)
representative point 20,198 rows total 989,948 (+0.00%)
intersects in NAD83: 28,567 rows
For census blocks the identifier join is better still, because a block's GEOID contains its tract. The point method is what to use for zones that are not part of the census hierarchy.
Example 3 — interpolation that keeps or drops the total
import numpy as np
from shapely.geometry import box
from tobler.area_weighted import area_interpolate

tract_pop = blocks.dissolve(by=blocks.GEOID20.str[:11], aggfunc={"POP20": "sum"}).reset_index(drop=True)
xmin, ymin, xmax, ymax = tract_pop.total_bounds
cells = [box(x, y, x + 2000, y + 2000)
         for x in np.arange(xmin, xmax, 2000) for y in np.arange(ymin, ymax, 2000)]
state = gpd.read_file("cb_2023_us_state_20m.zip").query("STATEFP == '10'").to_crs(5070)
grid = gpd.clip(gpd.GeoDataFrame(geometry=cells, crs=5070), state).reset_index(drop=True)

for allocate in (True, False):
    est = area_interpolate(tract_pop, grid, extensive_variables=["POP20"], allocate_total=allocate)
    print(f"allocate_total={allocate}: total {est.POP20.sum():,.0f} of {tract_pop.POP20.sum():,} "
          f"({est.POP20.sum() / tract_pop.POP20.sum() - 1:+.2%})")
print(f"tract area {tract_pop.area.sum() / 1e6:,.0f} km², state outline {state.area.sum() / 1e6:,.0f} km²")
allocate_total=True: total 989,948 of 989,948 (-0.00%)
allocate_total=False: total 979,271 of 989,948 (-1.08%)
tract area 6,446 km², state outline 5,325 km²
The 1.08% difference is entirely the people in the parts of coastal tracts outside the state outline. Preserving the total is correct for this grid; it would be wrong for a target that genuinely excludes part of the source.
Example 4 — five official totals for one state
est = pd.read_csv("NST-EST2024-ALLDATA.csv", encoding="latin-1").set_index("NAME").loc["Delaware"]
states = load_level("acsdt5y2023-b01003.dat", "0400000US", [pop])[pop]
totals = {"2020 census blocks": int(blocks.POP20.sum()),
          "estimates base, April 2020": est.ESTIMATESBASE2020,
          "population estimate, July 2020": est.POPESTIMATE2020,
          "ACS 5-year, 2019–2023": states["10"],
          "population estimate, July 2023": est.POPESTIMATE2023}
for name, value in totals.items():
    print(f"{name:34}{value:>9,}")
2020 census blocks 989,948
estimates base, April 2020 989,955
population estimate, July 2020 991,928
ACS 5-year, 2019–2023 1,005,872
population estimate, July 2023 1,036,423
The population estimates are Vintage 2024, the series published in 2025; each new vintage revises the earlier years, so a July 2020 figure depends on which vintage it came from.
Example 5 — statistics that do not roll up, and totals that do not cover
poverty = pd.read_csv("acsdt5y2023-b17001.dat", sep="|", usecols=["GEO_ID", "B17001_E001", "B17001_E002"])
de = poverty[poverty.GEO_ID.str.startswith("1400000US10")]
rate = de.B17001_E002 / de.B17001_E001.where(de.B17001_E001 > 0)
print(f"poverty: summed counts {de.B17001_E002.sum() / de.B17001_E001.sum():.2%}, "
      f"mean of tract rates {rate.mean():.1%}, median {rate.median():.2%}")

income = load_level("acsdt5y2023-b19013.dat", "1400000US", ["B19013_E001"]).B19013_E001
nc = income[income.index.str.startswith("10003") & (income > 0)]      # negative values are codes
weights = load_level("acsdt5y2023-b01003.dat", "1400000US", [pop])[pop][nc.index]
county = load_level("acsdt5y2023-b19013.dat", "0500000US", ["B19013_E001"]).B19013_E001["10003"]
print(f"New Castle median income: published {county:,}, mean of tract medians {nc.mean():,.0f}, "
      f"population-weighted {(nc * weights).sum() / weights.sum():,.0f}")

b01003 = pd.read_csv("acsdt5y2023-b01003.dat", sep="|", dtype={"GEO_ID": str})
moe = b01003[b01003.GEO_ID.str.startswith("1400000US10003")].B01003_M001
print(f"tract margins: summed {moe.sum():,}, root sum of squares {np.sqrt((moe ** 2).sum()):,.0f}, "
      f"county {b01003.set_index('GEO_ID').B01003_M001['0500000US10003']}")

places = load_level("acsdt5y2023-b01003.dat", "1600000US", [pop])[pop]
in_places = places[places.index.str.startswith("10")]
print(f"{len(in_places)} places hold {in_places.sum():,} of {states['10']:,} ({in_places.sum() / states['10']:.1%})")
nation = load_level("acsdt5y2023-b01003.dat", "0100000US", [pop])[pop].iloc[0]
print(f"nation {nation:,}; 50 states + DC {states.drop('72').sum():,}; with Puerto Rico {states.sum():,}")
poverty: summed counts 10.73%, mean of tract rates 11.2%, median 8.56%
New Castle median income: published 89,901, mean of tract medians 92,705, population-weighted 96,812
tract margins: summed 85,143, root sum of squares 7,692, county -555555555
79 places hold 435,168 of 1,005,872 (43.3%)
nation 332,387,540; 50 states + DC 332,387,540; with Puerto Rico 335,642,425
Double counting and drifting interpolation
Why a published hierarchy can still fail to add
The ACS publishes each summary level from the same weighted responses, so the tracts of a county add to the county when every tract is published. When a tract has no published row, its population exists in the county total and nowhere in the tract table. The Suffolk and Ulster gaps — 79,296 and 3,904 people — match the missing tracts exactly, which is how you know the arithmetic is right and the table is incomplete.
Why polygon predicates double count
Adjacent census polygons share boundaries. Geometrically, two polygons that share an edge intersect, so intersects pairs each edge block with every tract along its edge: 28,647 pairs for 20,198 blocks. within requires the block to lie entirely inside, and separately digitised or generalised boundaries rarely agree to the last vertex, so thousands of blocks fail it. Only a point inside each block avoids both.
Why interpolated totals drift
Area weighting gives each target the share of a source zone's area that falls inside it. If the targets do not cover the whole source zone — a grid clipped to a coastline, a study area, a buffer — some of that area falls in no target, and its people vanish. Normalising over the covered area puts them back, on the assumption that the uncovered part holds nobody.
Why official totals disagree
A decennial count, an estimates base, an annual estimate and a five-year survey average are four different products answering "how many people?" for different moments with different methods. The ACS is controlled to population estimates, not to the census count, and its five-year value represents the whole period. Differences of 1–5% between them are expected; a single table should never mix them.
Rescaling, identifiers and representative points
- Rescaling to a parent hides missing children. Report the gap instead of spreading the difference.
- Use identifiers for census-to-census joins. A block's GEOID contains its tract, county and state.
- Representative points, not centroids. A centroid of an irregular block can lie outside it.
allocate_totaldefaults to True in tobler. Turn it off deliberately when losses are the answer.- Totals from different vintages differ by design. Boundary changes move people between areas.
- Controlled totals have no margin. A sum of tract margins is not an estimate of the county margin.
- Puerto Rico is in ACS national tables, and not in the 50 states plus DC. Filter one side to match the other.
- Check exact equality before allowing a tolerance. ACS tract populations added exactly to every complete county here, so any non-zero difference was worth explaining.
Internal links
- How to aggregate survey estimates and their margins of error — combining counts and margins correctly
- Census geographies explained: blocks, tracts, output areas and why they nest — which areas are meant to add up
- How to redistribute population with dasymetric mapping — interpolation that preserves totals and places people better
- How to compare census years across changed boundaries — why totals can be right while tracts are wrong
- Margins of error explained: why survey estimates need their uncertainty — controlled totals and their codes
- How to interpolate to polygons instead of a grid — area weighting in detail
- My spatial join returns duplicate rows — the general form of double counting
- Spatial predicates explained: intersects, within, contains and the rest — what each predicate really tests
FAQ
Why do my tract populations not add up to the county?
Usually because tracts are missing from the table. In the 2023 ACS, Suffolk and Ulster counties in New York were short by 79,296 and 3,904 people, the populations of 15 tracts listed in the geography file but not published.
Why does my spatial join count more people than live in the state?
The join used intersects, which matches blocks to every tract they touch along shared boundaries. Delaware's blocks joined that way summed to 1,584,738 against a real 989,948; joining each block's representative point gave the exact total.
Why does areal interpolation lose people?
The target zones do not cover all of each source zone, so part of its area — and its people — falls outside every target. With allocate_total=False, a grid clipped to Delaware's outline lost 1.08% of the population.
Why are there several different population totals for the same place?
They come from different products: the census count, the estimates base, annual estimates and the ACS five-year average. For Delaware they ranged from 989,948 to 1,036,423, and none of them is wrong.
Can I average tract rates to get a county rate?
No. Sum the numerators and denominators first. Delaware's poverty rate from counts is 10.73%, while the unweighted mean of its tract rates is 11.2%.
Should I rescale tract values so they match the county total?
Not when the difference comes from missing tracts. Rescaling spreads the absent tracts' population over the ones that exist; report the gap instead.