
Boundary Changes Over Time: Why Two Census Years Do Not Line Up
On this page
Problem statement
Census geography is redrawn every decade. Between 2010 and 2020 the United States went from 74,134 census tracts to 85,528. The Census Bureau's relationship file records 22,893 tract codes that were new in 2020 and 11,499 codes from 2010 that were retired.
A join on GEOID between a 2010 table and 2020 boundaries matches 62,635 tracts and looks as if it mostly worked. It did not. Measured against the relationship file, 8,138 of those matching codes cover an area that changed by more than 1%. The code survived; the place it describes did not.
Reading the change is harder than it looks. Taken literally, the same relationship file says 43.6% of 2010 tracts overlap more than one 2020 tract. Most of that is digitising noise: a quarter of the file's rows are slivers smaller than 1% of both tracts, with a median area of 6,195 m². A comparison across census years has to separate real redrawing from those slivers, renamed codes and recoded counties before it can say anything about change.
Quick answer
Load the tract relationship file, ignore overlaps below a threshold, and count how each 2010 tract maps to 2020:
import pandas as pd

rel = pd.read_csv("tab20_tract20_tract10_natl.txt", sep="|", dtype=str,
                  encoding="utf-8-sig")
area = [c for c in rel.columns if c.startswith("AREA")]
rel[area] = rel[area].apply(pd.to_numeric)

part = rel["AREALAND_PART"] + rel["AREAWATER_PART"]
rel["share_of_10"] = part / (rel["AREALAND_TRACT_10"] + rel["AREAWATER_TRACT_10"])
rel["share_of_20"] = part / (rel["AREALAND_TRACT_20"] + rel["AREAWATER_TRACT_20"])

real = rel[(rel["share_of_10"] >= 0.01) | (rel["share_of_20"] >= 0.01)]
targets = real.groupby("GEOID_TRACT_10")["GEOID_TRACT_20"].nunique()
print(f"{(targets > 1).mean():.1%} of 2010 tracts feed more than one 2020 tract")
21.8% of 2010 tracts feed more than one 2020 tract
With a 1% threshold the national figure falls from 43.6% to 21.8%. Classified, the 74,134 tracts of 2010 were 53,073 one-to-one, 7,991 split, 4,904 merged and 8,166 part of a more complex rearrangement.
Stable units, four kinds of change, the relationship file
1. Know which units are meant to be stable
The Census Bureau describes tracts as "small, relatively permanent statistical subdivisions of a county", with a population between 1,200 and 8,000 and an optimum of 4,000. Block groups sit inside tracts with 600 to 3,000 people. Blocks are rebuilt from scratch every census.
Stability is therefore a matter of degree. A block code from 2010 means nothing in 2020. A tract code usually means the same place. The two have to be treated differently.
2. Recognise the four kinds of change
Every 2010 tract falls into one of four patterns:
- One-to-one — the same area, usually the same code.
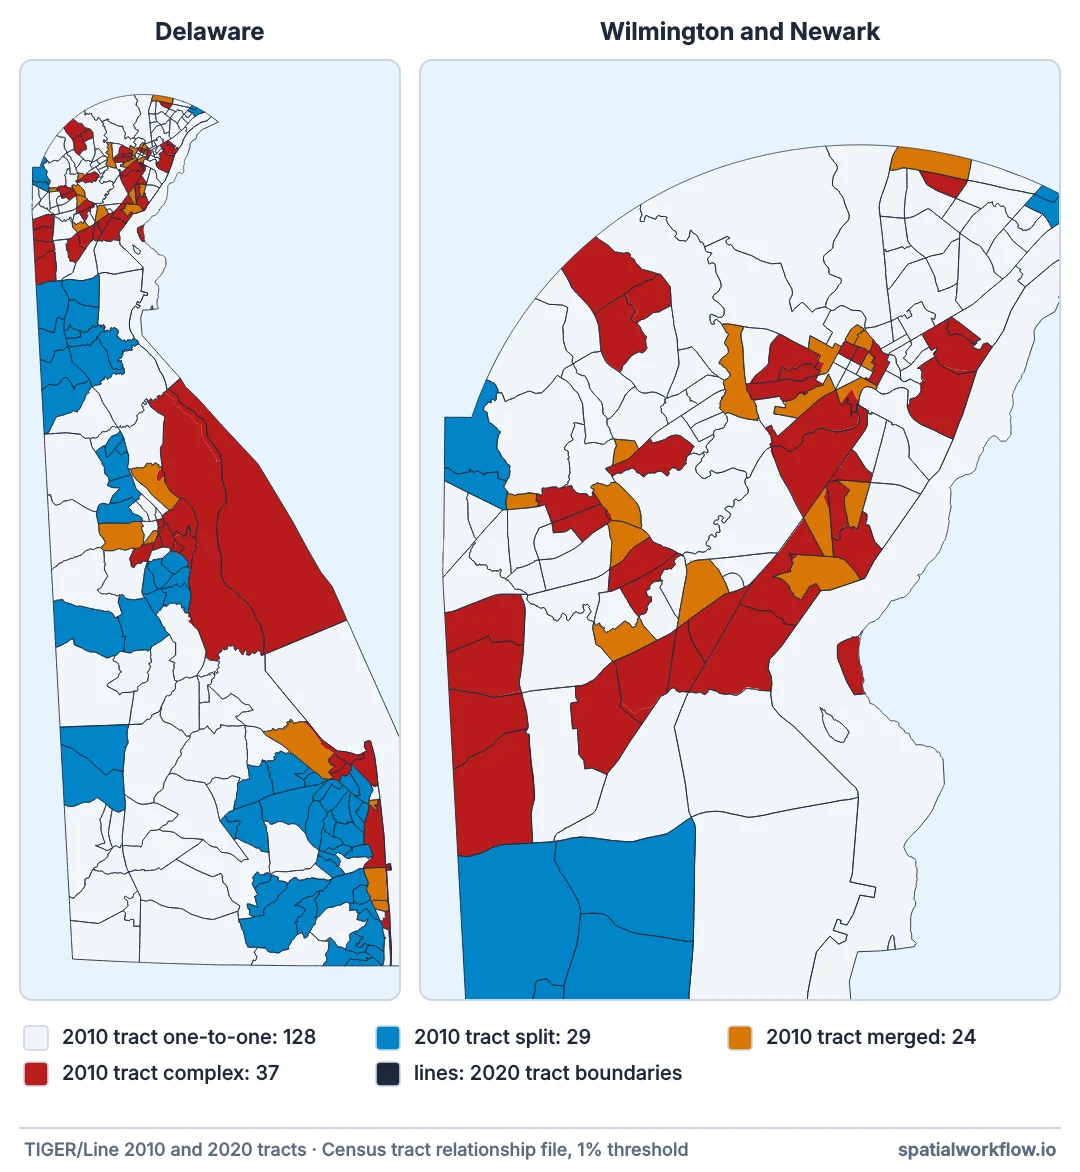
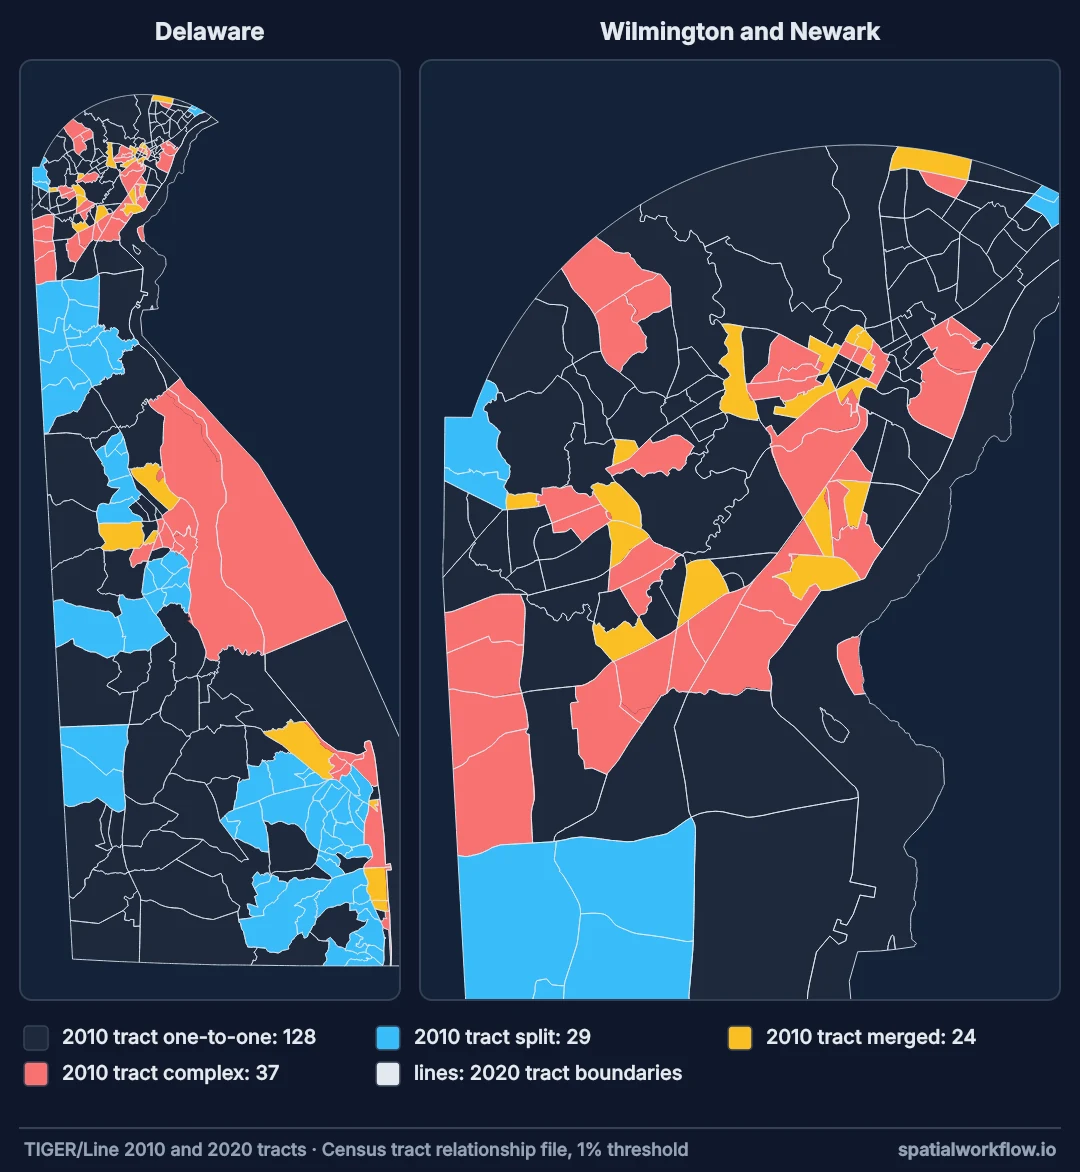
- Split — growth pushed a tract past the size limit and it became several. Tract 402.02 in Kent County, Delaware, became 402.04, 402.05 and 402.06.
- Merged — decline pushed tracts below the limit and they were combined.
- Complex — boundaries moved so that pieces of several old tracts form several new ones.
In Delaware, with a 1% threshold, the 218 tracts of 2010 were 128 one-to-one, 29 split, 24 merged and 37 complex. The split, merged and complex tracts held 411,829 of the state's 897,934 people in 2010, which is 46%.
3. Read the relationship file row by row
The tract relationship file has one row for every pair of tracts that share any area. Each row names the 2020 tract and the 2010 tract and gives the land and water area of their intersection:
cols = ["GEOID_TRACT_20", "GEOID_TRACT_10", "AREALAND_PART", "share_of_10", "share_of_20"]
print(rel[rel.GEOID_TRACT_20 == "09001010201"][cols].round(6).to_string(index=False))
GEOID_TRACT_20 GEOID_TRACT_10 AREALAND_PART share_of_10 share_of_20
09001010201 09001010201 11254407 0.999574 0.999943
09001010201 09001010300 650 0.000067 0.000057
The second row is typical. Two tracts in Fairfield County, Connecticut, share 650 m² of land: 0.0067% of the old tract. Nothing moved between them in any meaningful sense.
4. Separate real change from slivers
The threshold you choose changes the answer a great deal:
overlap threshold   2010 tracts feeding >1   2020 tracts drawing on >1
none                        32,288 (43.6%)             28,273 (33.1%)
0.1%                        23,954 (32.3%)             17,455 (20.4%)
1%                          16,157 (21.8%)              7,652  (8.9%)
5%                          11,968 (16.1%)              2,477  (2.9%)
With no threshold, 28,360 tracts are classified as complex. At 1% that falls to 8,166. The slivers come from lines being redrawn, not from tracts being reorganised. When the same road boundary is digitised a little differently in two vintages, the file records a thin shared strip.
5. Judge change by people, not by area
Area is a poor measure of what matters. In Delaware, 150 of the 433 relationship rows (35%) contained nobody at all in 2010, measured by allocating 2010 block populations to each piece.
A rule based on people — a 2010 tract counts as divided only if at least 1% of its residents end up in a second 2020 tract — flagged 44 Delaware tracts. The 1% area rule flagged 66, and the 5% area rule flagged 45. For this state, a 5% area threshold happened to land close to the population rule. Do not assume that holds elsewhere; compute it from blocks where you can.
6. Watch for codes that change without the boundaries
In 2022 Connecticut replaced its eight counties with nine planning regions as county-equivalents, and every tract GEOID in the state changed. Compared by geometry, 874 of the state's 884 tracts in the 2022 TIGER/Line file are within 1% of a 2020 tract with the same tract code. The GEOIDs have no match at all: 0 of 884 are shared.
A join that fails for an entire state is a coding change. A join that succeeds for a tract whose area changed is a boundary change, and that one gives no warning.
7. Choose how to compare the two years
Once you know what changed, there are three defensible choices:
- Restrict the comparison to one-to-one tracts. This is simple, but in Delaware it drops the 46% of 2010 residents who lived in tracts that changed.
- Crosswalk one year onto the other's boundaries using blocks. This is the accurate route, covered in the how-to guide on comparing census years.
- Aggregate both years to units that did not change, such as counties.
Weighting by area alone is not on the list. In Delaware it moved 5% of the population into the wrong 2020 tract, and it reversed the direction of change — growth shown as decline or decline as growth — in 32 of the 262 tracts.
Classifying Delaware's 2010 tracts against 2020
The data used on this page
The Census Bureau's national 2020–2010 tract relationship file; for Delaware, the 2010 blocks with their 2010 population (tabblock2010_10_pophu.zip), the 2020 blocks with POP20, and the 2020 TIGER/Line tracts; for Connecticut, the 2020 and 2022 TIGER/Line tracts.
import os
import urllib.request

G = "https://www2.census.gov/geo/"
files = {
    "tab20_tract20_tract10_natl.txt": G + "docs/maps-data/data/rel2020/tract/tab20_tract20_tract10_natl.txt",
    "tabblock2010_10_pophu.zip": G + "tiger/TIGER2010BLKPOPHU/tabblock2010_10_pophu.zip",
    "tl_2020_10_tabblock20.zip": G + "tiger/TIGER2020/TABBLOCK20/tl_2020_10_tabblock20.zip",
    "tl_2020_10_tract.zip": G + "tiger/TIGER2020/TRACT/tl_2020_10_tract.zip",
    "tl_2020_09_tract.zip": G + "tiger/TIGER2020/TRACT/tl_2020_09_tract.zip",
    "tl_2022_09_tract.zip": G + "tiger/TIGER2022/TRACT/tl_2022_09_tract.zip",
}
for name, url in files.items():
    if not os.path.exists(name):
        urllib.request.urlretrieve(url, name)
print("files ready")
files ready
Example 1 — loading the relationship file with overlap shares
import numpy as np
import pandas as pd


def load_tract_relationship(path):
    """The 2020-2010 tract relationship file with overlap shares."""
    rel = pd.read_csv(path, sep="|", dtype=str, encoding="utf-8-sig")
    area = ["AREALAND_TRACT_20", "AREAWATER_TRACT_20", "AREALAND_TRACT_10",
            "AREAWATER_TRACT_10", "AREALAND_PART", "AREAWATER_PART"]
    rel[area] = rel[area].apply(pd.to_numeric)
    part = rel["AREALAND_PART"] + rel["AREAWATER_PART"]
    rel["share_of_10"] = part / (rel["AREALAND_TRACT_10"] + rel["AREAWATER_TRACT_10"])
    rel["share_of_20"] = part / (rel["AREALAND_TRACT_20"] + rel["AREAWATER_TRACT_20"])
    return rel
Reading with dtype=str keeps the GEOIDs intact, and utf-8-sig strips the byte-order mark the Census Bureau puts on the first header. Without that, the first column is named OID_TRACT_20.
Example 2 — classifying each 2010 tract
def classify_changes(rel, threshold=0.01):
    """Label each 2010 tract one-to-one, split, merged or complex."""
    real = rel[(rel["share_of_10"] >= threshold) | (rel["share_of_20"] >= threshold)]
    targets = real.groupby("GEOID_TRACT_10")["GEOID_TRACT_20"].nunique()
    sources = real.groupby("GEOID_TRACT_20")["GEOID_TRACT_10"].nunique()
    real = real.assign(n_targets=real["GEOID_TRACT_10"].map(targets),
                       n_sources=real["GEOID_TRACT_20"].map(sources))
    per_tract = real.groupby("GEOID_TRACT_10").agg(n_targets=("n_targets", "first"),
                                                   max_sources=("n_sources", "max"))
    per_tract["change"] = np.select(
        [(per_tract.n_targets == 1) & (per_tract.max_sources == 1),
         (per_tract.n_targets > 1) & (per_tract.max_sources == 1),
         (per_tract.n_targets == 1) & (per_tract.max_sources > 1)],
        ["one-to-one", "split", "merged"], "complex")
    return per_tract


rel = load_tract_relationship("tab20_tract20_tract10_natl.txt")
print("threshold   one-to-one    split   merged   complex")
for label, t in (("none", 0), ("1%", 0.01), ("5%", 0.05)):
    c = classify_changes(rel, t).change.value_counts()
    print(f"{label:9} {c.get('one-to-one', 0):12,} {c.get('split', 0):8,} {c.get('merged', 0):8,} {c.get('complex', 0):9,}")
threshold one-to-one split merged complex
none 32,177 3,928 9,669 28,360
1% 53,073 7,991 4,904 8,166
5% 60,125 9,496 2,041 2,472
Example 3 — codes that survived while their tract changed
def same_code_different_shape(rel, tolerance=0.99):
    """GEOIDs used in both years whose area changed by more than 1 - tolerance."""
    same = rel[rel["GEOID_TRACT_10"] == rel["GEOID_TRACT_20"]]
    changed = same[(same["share_of_10"] < tolerance) | (same["share_of_20"] < tolerance)]
    return sorted(changed["GEOID_TRACT_20"])
moved = same_code_different_shape(load_tract_relationship("tab20_tract20_tract10_natl.txt"))
print(len(moved))8138
These are the tracts a GEOID join matches without complaint. A time series built on them compares two different areas under one label.
Example 4 — the national counts, the thresholds, and Delaware by people
import geopandas as gpd

t10, t20 = rel.GEOID_TRACT_10.dropna().unique(), rel.GEOID_TRACT_20.dropna().unique()
print(f"tracts: {len(t10):,} in 2010, {len(t20):,} in 2020; new codes {len(set(t20) - set(t10)):,}, "
      f"retired {len(set(t10) - set(t20)):,}, shared {len(set(t10) & set(t20)):,}")
sliver = (rel.share_of_10 < 0.01) & (rel.share_of_20 < 0.01)
print(f"sliver rows: {sliver.mean():.1%}, median area {(rel.AREALAND_PART + rel.AREAWATER_PART)[sliver].median():,.0f} m²")
print("threshold   2010 feeding >1   2020 drawing on >1")
for label, t in (("none", 0), ("0.1%", 0.001), ("1%", 0.01), ("5%", 0.05)):
    real = rel[(rel.share_of_10 >= t) | (rel.share_of_20 >= t)] if t else rel
    a = (real.groupby("GEOID_TRACT_10").GEOID_TRACT_20.nunique() > 1)
    b = (real.groupby("GEOID_TRACT_20").GEOID_TRACT_10.nunique() > 1)
    print(f"{label:9} {a.sum():8,} ({a.mean():.1%}) {b.sum():12,} ({b.mean():.1%})")

# Delaware: 2010 block populations placed in 2020 tracts
de = rel[rel.GEOID_TRACT_10.str.startswith("10", na=False)]
b10 = gpd.read_file("tabblock2010_10_pophu.zip")
b10["t10"] = b10.STATEFP10 + b10.COUNTYFP10 + b10.TRACTCE10
tr20 = gpd.read_file("tl_2020_10_tract.zip")[["GEOID", "geometry"]].to_crs(b10.crs)
pts = b10.set_geometry(b10.representative_point())
b10 = b10.assign(t20=gpd.sjoin(pts, tr20, predicate="within").GEOID.reindex(b10.index))
flows = b10.groupby(["t10", "t20"]).POP10.sum()
pop10 = b10.groupby("t10").POP10.sum()
classes = classify_changes(de, 0.01).change
changed = classes.index[classes != "one-to-one"]
print(f"Delaware 2010 tracts at 1%: {classes.value_counts().to_dict()}; in changed tracts "
      f"{pop10.reindex(changed).sum():,} of {pop10.sum():,} people")
pairs = de.set_index(["GEOID_TRACT_10", "GEOID_TRACT_20"]).index
print(f"relationship rows with nobody in them: {(flows.reindex(pairs).fillna(0) == 0).sum()} of {len(pairs)}")
share = flows / pop10.reindex(flows.index.get_level_values(0)).to_numpy()
print(f"divided by people (>=1% of residents in a second tract): {(share[share >= 0.01].groupby(level=0).size() > 1).sum()}; "
      f"by 1% of area: {(classify_changes(de, 0.01).n_targets > 1).sum()}; "
      f"by 5% of area: {(classify_changes(de, 0.05).n_targets > 1).sum()}")

# area weighting against the block allocation
by_area = (de.assign(p=de.share_of_10 * de.GEOID_TRACT_10.map(pop10)).groupby("GEOID_TRACT_20").p.sum())
by_blocks = flows.groupby(level=1).sum()
idx = by_blocks.index.union(by_area.index)
diff = (by_area.reindex(idx, fill_value=0) - by_blocks.reindex(idx, fill_value=0)).abs().sum() / 2
b20 = gpd.read_file("tl_2020_10_tabblock20.zip", columns=["GEOID20", "POP20"], ignore_geometry=True)
pop20 = b20.groupby(b20.GEOID20.str[:11]).POP20.sum()
flip = np.sign(pop20 - by_area.reindex(pop20.index, fill_value=0)) != np.sign(pop20 - by_blocks.reindex(pop20.index, fill_value=0))
print(f"area weighting puts {diff / pop10.sum():.1%} of 2010 people in the wrong 2020 tract, "
      f"and reverses the direction of change in {flip.sum()} of {len(pop20)} tracts")

# Connecticut: new codes, same shapes
ct20 = gpd.read_file("tl_2020_09_tract.zip")[["GEOID", "TRACTCE", "geometry"]]
ct22 = gpd.read_file("tl_2022_09_tract.zip")[["GEOID", "TRACTCE", "geometry"]].to_crs(ct20.crs)
m = ct22.merge(ct20, on="TRACTCE", suffixes=("_22", "_20"))
m = m[~m.TRACTCE.duplicated(keep=False)]
g22, g20 = gpd.GeoSeries(m.geometry_22, crs=ct20.crs).to_crs(3857), gpd.GeoSeries(m.geometry_20, crs=ct20.crs).to_crs(3857)
same = (g22.symmetric_difference(g20, align=False).area / g20.area) < 0.01
print(f"Connecticut 2022: {same.sum()} of {len(ct22)} tracts within 1% of the 2020 tract with the same code; "
      f"GEOIDs shared: {len(set(ct22.GEOID) & set(ct20.GEOID))}")
tracts: 74,134 in 2010, 85,528 in 2020; new codes 22,893, retired 11,499, shared 62,635
sliver rows: 25.5%, median area 6,195 m²
threshold 2010 feeding >1 2020 drawing on >1
none 32,288 (43.6%) 28,273 (33.1%)
0.1% 23,954 (32.3%) 17,455 (20.4%)
1% 16,157 (21.8%) 7,652 (8.9%)
5% 11,968 (16.1%) 2,477 (2.9%)
Delaware 2010 tracts at 1%: {'one-to-one': 128, 'complex': 37, 'split': 29, 'merged': 24}; in changed tracts 411,829 of 897,934 people
relationship rows with nobody in them: 150 of 433
divided by people (>=1% of residents in a second tract): 44; by 1% of area: 66; by 5% of area: 45
area weighting puts 5.0% of 2010 people in the wrong 2020 tract, and reverses the direction of change in 32 of 262 tracts
Connecticut 2022: 874 of 884 tracts within 1% of the 2020 tract with the same code; GEOIDs shared: 0
Why tracts are redrawn and files are full of slivers
Why tracts are redrawn every ten years
Tracts are defined by population. The Census Bureau's glossary notes that they "occasionally are split due to population growth or merged as a result of substantial population decline". A tract that has grown well past 8,000 people no longer fits the criteria, so the next census divides it.
The Delaware split above kept its parent's base number: 402.02 became 402.04, 402.05 and 402.06, so the children look related. Nothing in a merged or complex rearrangement's codes tells you which old tracts it drew on; only the relationship file does.
Why the relationship file is full of slivers
The relationship files are computed by intersecting two sets of polygons. Any two lines that represent the same boundary but are digitised slightly differently produce a thin intersection. Across the country that adds up to 32,223 rows, 25.5% of the file, each under 1% of both tracts.
The file reports them faithfully because it does not know the lines were meant to be the same. Filtering them is the user's decision, which is why every count in this guide is quoted at a stated threshold.
Why a surviving code is not a promise
A GEOID identifies a tract within one vintage. Nothing in the numbering guarantees that the area stays fixed across vintages: a boundary can move a street over, or take in part of a neighbour, while the code stays the same.
Measured, 8,138 of the 62,635 codes used in both 2010 and 2020 changed shape by more than 1%. For analyses that need a fixed area, the relationship file is the reliable test, not the code.
Why area weighting is not a comparison method
Area weighting assumes people are spread evenly within a tract, and they rarely are. A tract that loses a large rural area to a neighbour loses little population but a lot of area. Area weighting then moves people out with the land.
In Delaware, as the crosswalk guide measured, that put 45,362 of 897,934 people, or 5.05%, into the wrong 2020 tract. The state total was still exact, because area weights always preserve totals. That is why this error never shows up in a total check.
Why Connecticut changed every code at once
County codes are part of every tract GEOID. When planning regions (county codes 110–190) replaced the old counties (001–015) as Connecticut's county-equivalents in 2022 data products, every tract, block group and block GEOID in the state changed. The tract codes themselves survived, and the geometry barely moved.
Recoding the county part of the GEOID restores the join. No areal method is needed.
Blocks, area-based weights and thresholds
- Blocks are not comparable across censuses. Delaware had 24,115 blocks in 2010 and 20,198 in 2020 (the crosswalk guide counts them), and the numbering was rebuilt.
- Relationship files are area-based. They contain no population, so decide splits by allocating block counts to the pieces.
- The threshold is a choice. Quote it with any count of changed tracts; at none, 1% and 5% the national share of dividing tracts was 43.6%, 21.8% and 16.1%.
- Water counts in the total area. Coastal tracts can look changed because a shoreline was redrawn; test land area separately.
- Treat a GEOID as unique only within its vintage. 11,499 codes from 2010 were retired, and 22,893 appeared for the first time in 2020.
- County-equivalents change too. Connecticut in 2022 is the large recent case, and every tract GEOID in the state changed with it.
- Zero-population tracts exist. Delaware has four in 2020, with codes in the 9800 and 9900 ranges, so growth rates for them are undefined.
- A one-to-one tract can still gain or lose a block. "One-to-one at 1%" means under 1% of area moved, not zero.
Internal links
- Census geographies explained: blocks, tracts, output areas and why they nest — the hierarchy these changes happen within
- Census identifiers explained: GEOIDs, codes and the leading zero problem — what a GEOID encodes
- How to compare census years across changed boundaries — the block-based crosswalk
- Fixing census data that does not match the boundary file year — the join failures this causes
- How to download census boundaries in Python — getting both vintages
- How to interpolate to polygons instead of a grid — the general method, and its assumptions
- How to redistribute population with dasymetric mapping — better than area when blocks are unavailable
- The modifiable areal unit problem explained — why the units change the answer
- Fixing census totals that do not add up after aggregation — the other way reshaped units mislead
FAQ
How many census tracts changed between 2010 and 2020?
It depends on the threshold. Ignoring overlaps below 1% of either tract, 21.8% of 2010 tracts fed more than one 2020 tract. Counting every sliver, 43.6% did.
Does the same GEOID mean the same area in both years?
Not reliably. Of the 62,635 tract codes used in both 2010 and 2020, 8,138 cover an area that changed by more than 1%.
Where does the Census Bureau publish the changes?
In relationship files under the rel2020 directory of www2.census.gov. There is one for tracts and one for blocks, each listing every pair of old and new units with the area they share.
Why do the relationship files list so many tiny overlaps?
Because they intersect two separately digitised sets of lines. A quarter of the national tract file's rows are under 1% of both tracts, with a median of 6,195 m².
Can I just use area weighting to compare years?
It preserves totals and misplaces people. In Delaware it moved 5% of the population into the wrong tract and reversed the direction of change for 31 of 262 tracts.
Why did every Connecticut tract GEOID change in 2022?
Connecticut's planning regions replaced its counties as county-equivalents, and the county code is part of every tract GEOID. The tract geometry was almost unchanged.