
How to Compare Census Years Across Changed Boundaries
On this page
Problem statement
You have 2010 and 2020 census counts and want to know which tracts grew. The two years use different tracts. Delaware had 218 tracts in 2010 and 262 in 2020, and a join on GEOID matches only 179 of the 262. The other 83 are new codes with no 2010 counterpart.
The quick fix most people reach for is area weighting: split each 2010 tract's people across the 2020 tracts it overlaps, in proportion to shared area. Measured against a block-based crosswalk, it put 43,665–45,465 people (4.9–5.1%) in the wrong tract. For 27 to 34 of the 262 tracts, depending on the variant, it reversed the direction of change. The state total stayed exactly right the whole time, so a total check would never have caught it.
The Census Bureau publishes everything needed to do this properly: 2010 block counts and a file that maps every 2010 block onto 2020 blocks. The crosswalk takes 0.1 s.
Quick answer
import zipfile
import numpy as np
import pandas as pd
import geopandas as gpd

# 2010 block counts (POP10, HOUSING10)
blocks10 = gpd.read_file("tabblock2010_10_pophu.zip", ignore_geometry=True)
counts = blocks10.set_index("BLOCKID10")[["POP10", "HOUSING10"]]

# 2010 block -> 2020 block relationship file
archive = zipfile.ZipFile("TAB2010_TAB2020_ST10.zip")
rel = pd.read_csv(archive.open(archive.namelist()[0]), sep="|", dtype=str,
                  encoding="utf-8-sig")
for col in ["AREALAND_2010", "AREALAND_INT"]:
    rel[col] = pd.to_numeric(rel[col])
rel["block10"] = rel.STATE_2010 + rel.COUNTY_2010 + rel.TRACT_2010 + rel.BLK_2010
rel["tract20"] = rel.STATE_2020 + rel.COUNTY_2020 + rel.TRACT_2020
rel["weight"] = rel.AREALAND_INT / rel.AREALAND_2010.where(rel.AREALAND_2010 > 0)

moved = rel.merge(counts, left_on="block10", right_index=True)
pop10_in_2020_tracts = (moved["POP10"] * moved["weight"].fillna(0)).groupby(moved["tract20"]).sum()
Measured on Delaware: 897,934 people in 2010, all of them placed in 262 2020 tracts. Only 104 of the 24,115 2010 blocks straddle a 2020 tract line, and they hold 4,433 people. Everyone else moves as a whole block, so there is no areal assumption to be wrong about. (The quick version drops blocks that are entirely water; Example 1 handles them.)
What you get — from The data used on this page
{'tabblock2010_10_pophu.zip': '12.5 MB', 'TAB2010_TAB2020_ST10.zip': '0.3 MB', 'tl_2010_10_tract10.zip': '1.0 MB', 'tl_2020_10_tract.zip': '1.1 MB', 'tl_2020_10_tabblock20.zip': '21.5 MB'}
Earlier onto later, block by block
1. Choose the direction
Bring the earlier year onto the later boundaries. The 2020 tracts are the ones current tables are published on and current maps are drawn with, so a 2010 → 2020 crosswalk produces something you can join to everything else.
2. Get the earlier year at the smallest unit available
For 2010, the Census Bureau's TIGER2010BLKPOPHU series has block polygons carrying POP10 and HOUSING10:
blocks10 = gpd.read_file("tabblock2010_10_pophu.zip", ignore_geometry=True)
print(len(blocks10), blocks10["POP10"].sum())      # 24115 897934
You do not need the geometry for a relationship-file crosswalk. ignore_geometry=True reads the attribute table only.
3. Download the block relationship file
The 2010-to-2020 tabulation block relationship files are published per state under rel2020/t10t20/. Delaware's has 27,278 rows. Each row is one intersection of a 2010 block and a 2020 block, with the land and water area they share (AREALAND_INT, AREAWATER_INT).
4. Build weights from land area and check they sum to one
Use the land share of each 2010 block, not its total area. People live on land, and a coastal block's water area would otherwise pull residents offshore. Blocks that are entirely water fall back to total area. Renormalise within each block and confirm that every block's weights sum to exactly 1 (Example 1 does this; the largest deviation measured was 0.0).
5. Crosswalk, then check nothing leaked
pop10_in_2020 = crosswalk(counts, block_weights("TAB2010_TAB2020_ST10.zip"))
print(pop10_in_2020.sum().to_dict())    # {'POP10': 897934.0, 'HOUSING10': 405885.0}
The function raises if any source block is missing from the weights and asserts that totals are preserved. Both checks are cheap. Without them, a crosswalk that silently lost a county can look perfectly sensible.
6. Compare with the shortcut you were tempted to use
Scored with the compare function from Example 3, as Example 4 runs it:
method                         people misallocated   median |%|   tracts >10% off
block crosswalk (reference)                     0         0.00                 0
tract land-area weights            43,665 (4.86%)         0.85                68
tract total-area weights           45,362 (5.05%)         1.02                74
tobler area_interpolate            45,465 (5.06%)         1.02                74
tobler.area_weighted.area_interpolate on the two TIGER tract layers took about half a second, and no tract differed from the relationship-file total-area weights by more than 54 people. The two area methods are the same calculation. What makes the block method better is that it uses where people actually were.
7. Compute change on one geography
pop20 = blocks20.groupby(blocks20["GEOID20"].str[:11])["POP20"].sum()
growth = pd.DataFrame({"pop10": pop10_in_2020["POP10"], "pop20": pop20})
growth["pct"] = (growth["pop20"] / growth["pop10"] - 1) * 100
In Delaware the median tract grew 4.8%. 64 tracts lost people and 18 grew by more than half. Four 2020 tracts have no residents at all, so their growth rate is undefined; filter or flag them before mapping.
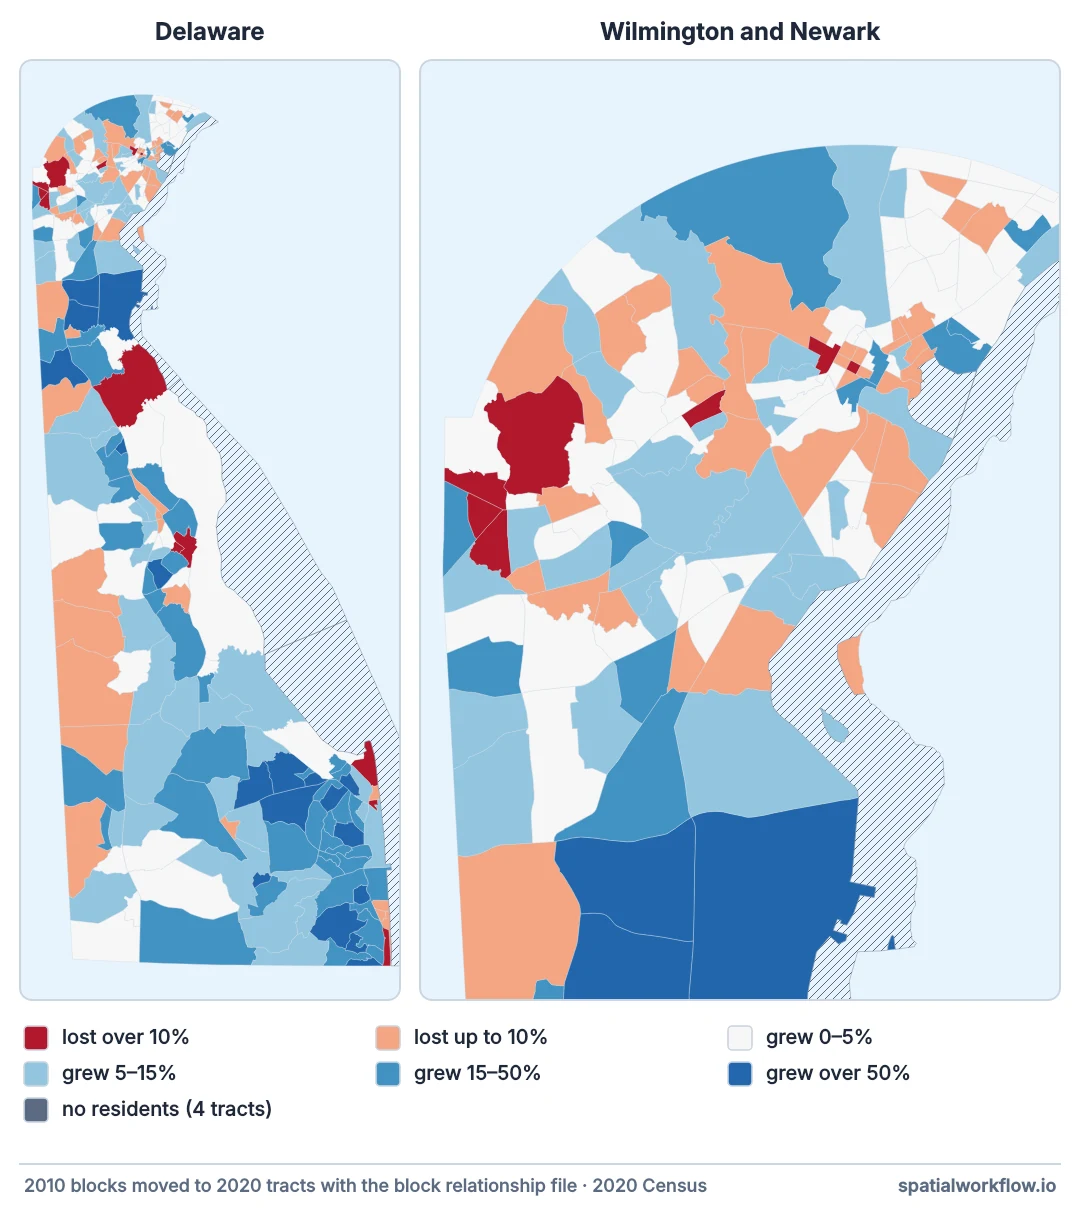
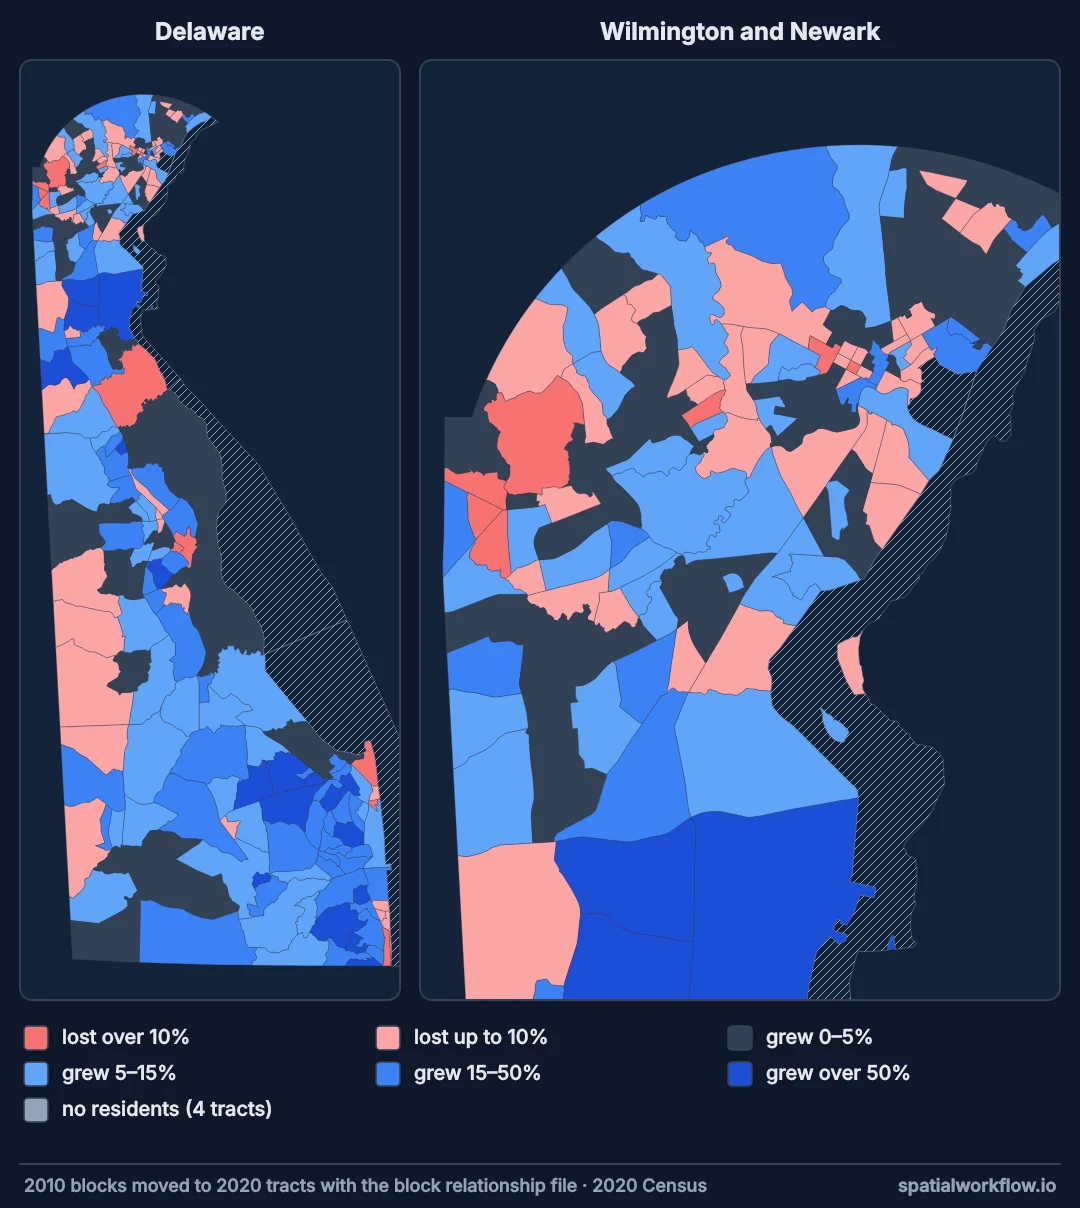
8. Crosswalk counts, never medians or rates
A median household income cannot be split by a weight. Crosswalk the numerator and denominator counts separately, then divide on the new geography. For survey tables that only exist as tract medians, use a published crosswalk at tract level and accept a less exact result.
A Delaware crosswalk that refuses to leak
The data used on this page
Delaware, from the Census Bureau: 2010 block polygons with POP10 and HOUSING10 (TIGER2010BLKPOPHU), the 2010-to-2020 tabulation block relationship file, 2010 and 2020 TIGER/Line tracts, and 2020 TIGER/Line blocks for POP20.
import os

import requests

T = "https://www2.census.gov/geo"
FILES = {
    "tabblock2010_10_pophu.zip": f"{T}/tiger/TIGER2010BLKPOPHU/tabblock2010_10_pophu.zip",
    "TAB2010_TAB2020_ST10.zip": f"{T}/docs/maps-data/data/rel2020/t10t20/TAB2010_TAB2020_ST10.zip",
    "tl_2010_10_tract10.zip": f"{T}/tiger/TIGER2010/TRACT/2010/tl_2010_10_tract10.zip",
    "tl_2020_10_tract.zip": f"{T}/tiger/TIGER2020/TRACT/tl_2020_10_tract.zip",
    "tl_2020_10_tabblock20.zip": f"{T}/tiger/TIGER2020/TABBLOCK20/tl_2020_10_tabblock20.zip",
}
for name, url in FILES.items():
    if not os.path.exists(name):
        r = requests.get(url, timeout=600)
        r.raise_for_status()
        open(name, "wb").write(r.content)
print({name: f"{os.path.getsize(name) / 1e6:.1f} MB" for name in FILES})
{'tabblock2010_10_pophu.zip': '12.5 MB', 'TAB2010_TAB2020_ST10.zip': '0.3 MB', 'tl_2010_10_tract10.zip': '1.0 MB', 'tl_2020_10_tract.zip': '1.1 MB', 'tl_2020_10_tabblock20.zip': '21.5 MB'}
Example 1 — block weights that always sum to one
import zipfile
import numpy as np
import pandas as pd


def block_weights(zip_path):
    """2010 block -> 2020 tract weights from the Census block relationship file."""
    archive = zipfile.ZipFile(zip_path)
    rel = pd.read_csv(archive.open(archive.namelist()[0]), sep="|", dtype=str,
                      encoding="utf-8-sig")
    area = ["AREALAND_2010", "AREAWATER_2010", "AREALAND_INT", "AREAWATER_INT"]
    rel[area] = rel[area].apply(pd.to_numeric)
    rel["block10"] = rel["STATE_2010"] + rel["COUNTY_2010"] + rel["TRACT_2010"] + rel["BLK_2010"]
    rel["tract20"] = rel["STATE_2020"] + rel["COUNTY_2020"] + rel["TRACT_2020"]

    # land share where the block has land, total-area share where it is all water
    rel["share"] = np.where(rel["AREALAND_2010"] > 0, rel["AREALAND_INT"],
                            rel["AREALAND_INT"] + rel["AREAWATER_INT"])
    weights = rel.groupby(["block10", "tract20"], as_index=False)["share"].sum()
    total = weights.groupby("block10")["share"].transform("sum")
    pieces = weights.groupby("block10")["share"].transform("size")
    weights["weight"] = np.where(total > 0, weights["share"] / total.where(total > 0), 1 / pieces)
    return weights[["block10", "tract20", "weight"]]
Grouping to 2020 tracts before normalising matters. A 2010 block that becomes three 2020 blocks in the same tract should carry one weight of 1.0, not three rows that each need summing later. Delaware's 27,278 block-to-block rows collapse to 24,220 block-to-tract weights.
Example 2 — a crosswalk that refuses to leak
def crosswalk(counts, weights, source="block10", target="tract20"):
    """Move additive counts onto the target geography and prove nothing leaked."""
    merged = weights.merge(counts, left_on=source, right_index=True, how="inner")
    unmatched = counts.index.difference(weights[source].unique())
    if len(unmatched):
        raise ValueError(f"{len(unmatched)} source units missing from the weights, "
                         f"holding {counts.loc[unmatched].sum().to_dict()}")
    moved = merged[counts.columns].mul(merged["weight"], axis=0).groupby(merged[target]).sum()
    drift = moved.sum() - counts.sum()
    assert (drift.abs() < 1e-6 * counts.sum().abs().clip(lower=1)).all(), drift
    return moved


print(crosswalk(counts, block_weights("TAB2010_TAB2020_ST10.zip")).head(3).round(1))
POP10 HOUSING10
tract20
10001040100 6541.0 2469.0
10001040201 5037.7 2021.4
10001040203 5017.0 2022.0
Fractional people are expected. They are the share of a straddling block assigned to each side. Round only for display.
Example 3 — scoring any other method against the reference
def compare(estimate, reference, label):
    """How far an estimate is from a reference crosswalk, in people and in tracts."""
    estimate = estimate.reindex(reference.index).fillna(0)
    error = estimate - reference
    pct = error.abs() / reference.where(reference > 0) * 100
    return pd.Series({
        "method": label,
        "people_misallocated": round(error.abs().sum() / 2),
        "share_misallocated_pct": round(error.abs().sum() / 2 / reference.sum() * 100, 2),
        "median_abs_pct": round(pct.median(), 2),
        "tracts_over_10pct": int((pct > 10).sum()),
    })
Half the sum of absolute errors is the number of people who ended up somewhere they were not. Every person placed wrongly is counted once as a surplus in one tract and once as a deficit in another.
Example 4 — the whole comparison, run end to end
import time
import geopandas as gpd
from tobler.area_weighted import area_interpolate

start = time.perf_counter()
weights = block_weights("TAB2010_TAB2020_ST10.zip")
reference = crosswalk(counts, weights)["POP10"]
print(f"weights and crosswalk: {time.perf_counter() - start:.2f} s")
dev = (weights.groupby("block10")["weight"].sum() - 1).abs().max()
print(f"{len(rel):,} relationship rows -> {len(weights):,} block-to-tract weights; largest deviation of a block's sum from 1: {dev:.1e}")
split = weights.loc[weights["weight"] < 1, "block10"].unique()
print(f"{len(split)} of {len(counts):,} 2010 blocks straddle a 2020 tract line, "
      f"holding {int(counts.loc[split, 'POP10'].sum()):,} people")

tract10 = counts["POP10"].groupby(counts.index.str[:11]).sum()
rel["AREAWATER_INT"] = pd.to_numeric(rel["AREAWATER_INT"])
rel["tract10"] = rel["block10"].str[:11]

def tract_area_weights(area):
    """The shortcut: split each whole 2010 tract by the area it shares with each 2020 tract."""
    shared = area.groupby([rel["tract10"], rel["tract20"]]).sum()
    share = shared / shared.groupby(level=0).transform("sum")
    return (share * tract10.reindex(share.index.get_level_values(0)).to_numpy()).groupby(level=1).sum()

t10 = gpd.read_file("tl_2010_10_tract10.zip").to_crs(5070)
t10["POP10"] = t10["GEOID10"].map(tract10)
t20 = gpd.read_file("tl_2020_10_tract.zip").to_crs(5070)
start = time.perf_counter()
tob = area_interpolate(t10, t20, extensive_variables=["POP10"])
seconds = time.perf_counter() - start
tob.index = t20["GEOID"]

print(f"tracts: {len(t10)} in 2010, {len(t20)} in 2020, {t20['GEOID'].isin(t10['GEOID10']).sum()} GEOIDs in both")
estimates = {"block crosswalk (reference)": reference,
             "tract land-area weights": tract_area_weights(rel["AREALAND_INT"]),
             "tract total-area weights": tract_area_weights(rel["AREALAND_INT"] + rel["AREAWATER_INT"]),
             "tobler area_interpolate": tob["POP10"]}
print(pd.DataFrame([compare(e, reference, k) for k, e in estimates.items()]).to_string(index=False))
land = estimates["tract land-area weights"].reindex(reference.index)
for tract in [(land - reference).abs().idxmax(), "10003014302"]:
    print(f"{tract}: blocks {reference[tract]:,.0f}, land-area weights {land[tract]:,.0f}")
print(f"tobler: {seconds:.2f} s; largest gap to total-area weights "
      f"{(tob['POP10'] - estimates['tract total-area weights'].reindex(tob.index)).abs().max():.0f} people")

blocks20 = gpd.read_file("tl_2020_10_tabblock20.zip", columns=["GEOID20", "POP20"], ignore_geometry=True)
pop20 = blocks20.groupby(blocks20["GEOID20"].str[:11])["POP20"].sum()
growth = pd.DataFrame({"pop10": reference, "pop20": pop20})
growth["pct"] = (growth["pop20"] / growth["pop10"] - 1) * 100
print(f"median tract change {growth['pct'].median():+.1f}%; {(growth['pct'] < 0).sum()} lost people; "
      f"{(growth['pct'] > 50).sum()} grew by more than half; {(growth['pop20'] == 0).sum()} with no residents")
for k, e in list(estimates.items())[1:]:
    flipped = np.sign(pop20 - e.reindex(pop20.index).fillna(0)) != np.sign(pop20 - reference.reindex(pop20.index))
    print(f"{k}: direction of change reversed in {int(flipped.sum())} tracts")
weights and crosswalk: 0.09 s
27,278 relationship rows -> 24,220 block-to-tract weights; largest deviation of a block's sum from 1: 0.0e+00
104 of 24,115 2010 blocks straddle a 2020 tract line, holding 4,433 people
tracts: 218 in 2010, 262 in 2020, 179 GEOIDs in both
method people_misallocated share_misallocated_pct median_abs_pct tracts_over_10pct
block crosswalk (reference) 0 0.00 0.00 0
tract land-area weights 43665 4.86 0.85 68
tract total-area weights 45362 5.05 1.02 74
tobler area_interpolate 45465 5.06 1.02 74
10003014301: blocks 1,310, land-area weights 5,009
10003014302: blocks 5,699, land-area weights 2,002
tobler: 0.36 s; largest gap to total-area weights 54 people
median tract change +4.8%; 64 lost people; 18 grew by more than half; 4 with no residents
tract land-area weights: direction of change reversed in 27 tracts
tract total-area weights: direction of change reversed in 33 tracts
tobler area_interpolate: direction of change reversed in 34 tracts
The direction count compares each method's sign of change with the reference's. Land-area weights reverse the fewest, and every variant reverses more than one tract in ten.
Why blocks make the crosswalk nearly exact
Why blocks make the crosswalk nearly exact
A block is a street block. Only 104 of Delaware's 24,115 2010 blocks were cut by a 2020 tract boundary, because tract boundaries overwhelmingly follow the same streets and streams that bound blocks. The other 24,011 blocks move whole.
Area weighting only has to guess for the 4,433 people in the straddling blocks. For them, guessing by land area within a single street block is a small error.
Why tract area weights fail where it matters
The worst tract under area weighting was 10003014301 in New Castle County. The block reference puts 1,310 of its 2020 area's 2010 residents there. Land-area weighting put 5,009, nearly four times as many, because it inherited a large piece of land from a parent tract whose people lived elsewhere.
Tracts that change are exactly the ones where growth or decline was uneven. The assumption of even spread is most wrong in the places the analysis is about.
Why the total never warns you
Every weighting scheme in this guide distributes each source unit's people across targets with weights summing to one. The total is preserved by construction: 897,934 in every row of the comparison table.
A correct total is necessary and not sufficient. The per-tract comparison against a reference is what reveals the 5%.
Why growth is more fragile than population
A 5% error in a count becomes a much larger error in a change. If a tract really grew 3% and area weighting overstates its 2010 base by 6%, it appears to have shrunk. That happened to 27 Delaware tracts under land-area weights and to 33 or 34 under the total-area variants. The sign of the change, usually the headline of the map, was wrong.
When you only have tract-level data
Survey data such as the ACS is not published for blocks. Allocate tract values with weights derived from block populations. Build them yourself from block counts and the relationship file, or use a published block-population-based crosswalk such as those from IPUMS NHGIS. That keeps most of the accuracy even when the data being moved is not itself block-level.
String codes, byte-order marks and water blocks
- Read every code column as a string. The relationship file's tract codes have leading zeros, and a numeric parse destroys them.
- Strip the byte-order mark. The files start with one;
encoding="utf-8-sig"avoids a first column namedSTATE_2010. - Some blocks are all water. Their land area is zero, so land weights divide by zero. Fall back to total area for those blocks.
- Straddling blocks produce fractional people. Round only after aggregating.
- Zero-population 2020 tracts exist. Delaware has four; exclude them from growth rates rather than dividing by zero.
- Medians cannot be crosswalked. Move counts and recompute.
- A GEOID join is not a crosswalk. It matched 179 tracts here and silently ignored whether their areas changed.
- The 2010 block file is large. Delaware's is 12 MB zipped; for a big state read only the attribute table.
Internal links
- Boundary changes over time: why two census years do not line up — what changed and how to classify it
- Fixing census data that does not match the boundary file year — when the failure is a join, not a comparison
- How to interpolate to polygons instead of a grid — area weighting, and its assumption
- How to redistribute population with dasymetric mapping — when there are no blocks to crosswalk with
- Fixing census totals that do not add up after aggregation — the totals checks that do and do not help
- How to download census boundaries in Python — both vintages of tracts
- How to aggregate survey estimates and their margins of error — combining ACS tracts after a crosswalk
- Census identifiers explained: GEOIDs, codes and the leading zero problem — building block and tract codes from parts
FAQ
What is a census crosswalk?
A table of weights that moves counts from one set of geographic units to another. Each source unit's weights across its targets sum to one, so totals are preserved.
Where do I get the 2010 to 2020 block relationship files?
From the Census Bureau at www2.census.gov/geo/docs/maps-data/data/rel2020/t10t20/, one zipped pipe-delimited file per state. Delaware's is 344 KB.
Is area weighting good enough?
Not for tract-level change. In Delaware it misallocated about 5% of the population and reversed the direction of change for 27 to 34 of 262 tracts, while the state total stayed exact.
Can I use tobler for this?
Yes for area weighting — area_interpolate on the two tract layers took about half a second — but it gives the same result as the relationship-file area weights. The accuracy gain comes from using block populations, not from the tool.
How do I compare median income across the two years?
You cannot crosswalk a median directly. Move the underlying counts, such as households by income band, and recompute, or restrict the comparison to tracts whose boundaries did not change.
Why is the crosswalked population not a whole number?
Blocks that straddle a new tract boundary are split by land area, so a tract can receive part of a block's population. Aggregate first and round for presentation only.