
How to Redistribute Population with Dasymetric Mapping
On this page
Problem statement
Population is published for census units, but questions are asked about other zones: a flood extent, a school catchment, a grid, a service area. The usual answer is area weighting, which splits a tract's people across the zones it overlaps in proportion to area. That assumes people are spread evenly across the tract, and they are not.
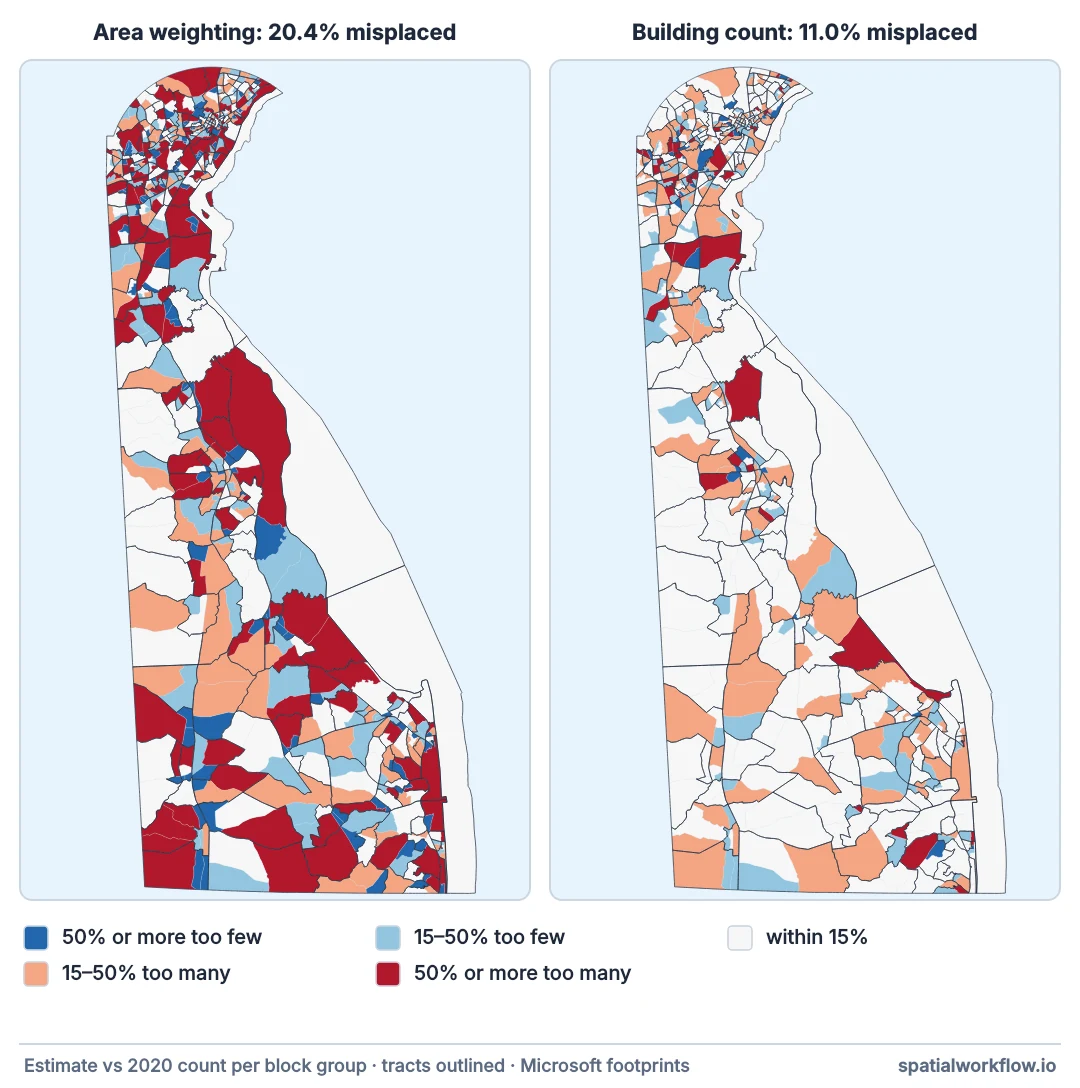
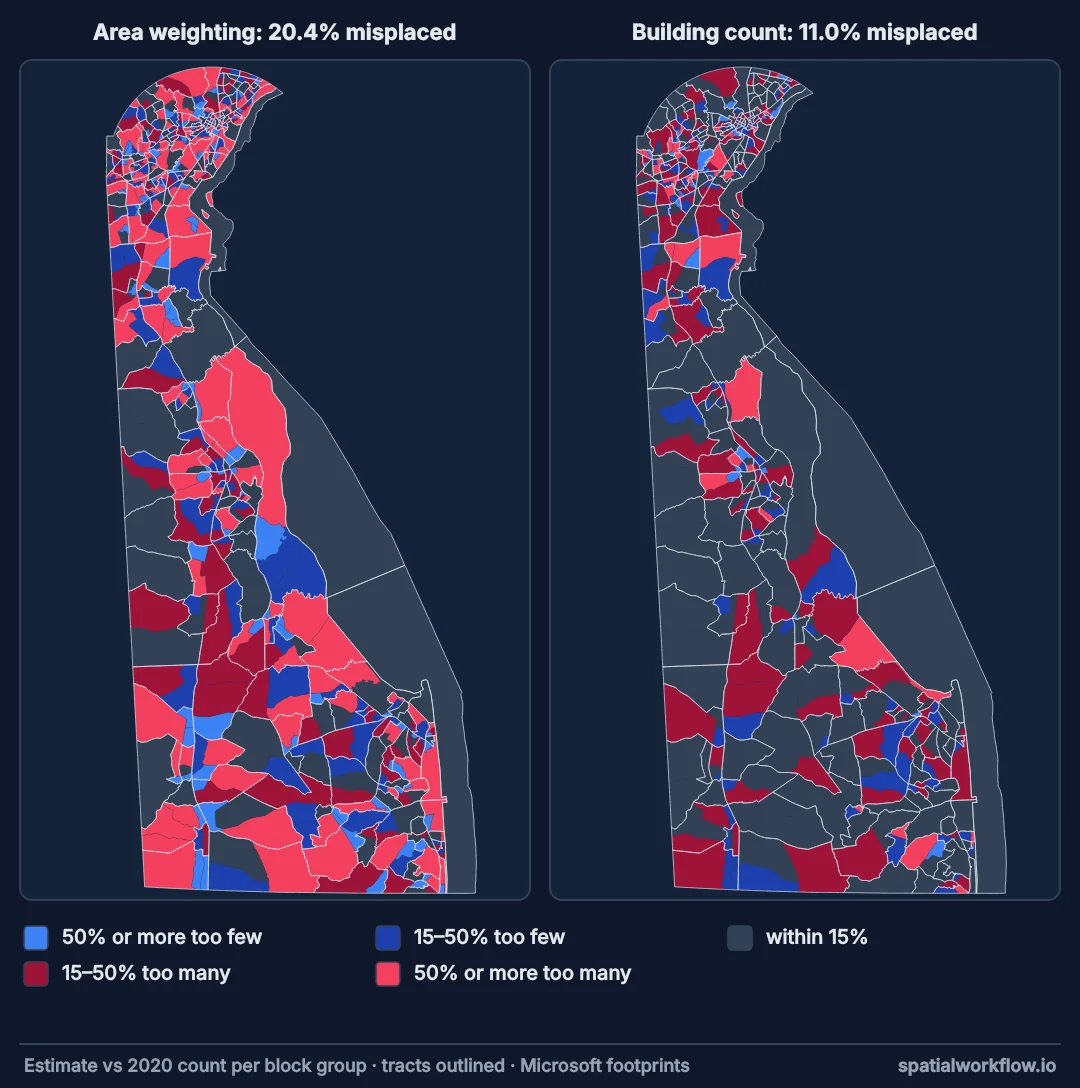
This guide tests the assumption where the answer is known. Delaware's 262 census tracts were redistributed to its 706 block groups, whose 2020 counts come from the census blocks. Area weighting put 202,169 people (20.4%) in the wrong block group, and the median block group was off by 34.6%.
Dasymetric mapping uses ancillary data to say where people can live within each source zone. A land-cover mask cut the error to 15.9%. Building footprints cut it to 11.0%. Removing water alone, the most common "improvement", took it from 20.4% to 20.2%.
Quick answer
With a land-cover raster, tobler does the whole thing in one call:
from tobler.dasymetric import masked_area_interpolate

estimate = masked_area_interpolate(
    tracts.to_crs(5070),                 # source zones with the counts
    block_groups.to_crs(5070),           # target zones
    raster="worldcover_30m.tif",         # ESA WorldCover, resampled to 30 m
    pixel_values=[50],                   # class 50 = built-up
    extensive_variables=["POP20"],
    nodata=0,
)
Measured on Delaware: about 10 s, total preserved at 989,948, and 169,046 people misallocated (17.1%) against 202,169 for plain area weighting.
With building footprints instead of a raster, the dasymetric() function in Example 1 took about a second and misallocated 108,530 people (11.0%).
What you get — from The data used on this page
WorldCover window 9,658 x 16,661 pixels, 6,548,876 built-up
Counts not rates, a scored test, then ancillary data
1. Redistribute counts, not rates
Dasymetric mapping splits an extensive quantity — people, households, housing units — across space. Medians, percentages and densities do not split. Redistribute the counts behind them and recompute on the target zones.
2. Build a test you can score
Pick a pair of geographies where the target totals are known. Census blocks sum exactly to block groups and tracts, so you can dissolve blocks into both and pretend you only had the tracts:
import geopandas as gpd

blocks = gpd.read_file("tl_2020_10_tabblock20.zip", columns=["GEOID20", "POP20"])
tracts = blocks.dissolve(by=blocks.GEOID20.str[:11], aggfunc={"POP20": "sum"})
groups = blocks.dissolve(by=blocks.GEOID20.str[:12], aggfunc={"POP20": "sum"})
truth = groups["POP20"]
The TIGER/Line 2020 block file already carries POP20, so no API call is needed. Dissolving Delaware's 20,198 blocks took about 3 s.
3. Measure the baseline first
from tobler.area_weighted import area_interpolate

aw = area_interpolate(tracts.to_crs(5070), groups.to_crs(5070),
                      extensive_variables=["POP20"])
Half a second, and 20.4% of people in the wrong block group. That is the number any ancillary dataset has to beat. Without it you cannot tell whether a mask helped.
4. Choose the ancillary data
Two open options cover most of the world:
- Land cover. ESA WorldCover 2021 is a 10 m global classification, published as cloud-optimised GeoTIFF tiles on AWS. Class 50 is built-up. Two tiles cover Delaware.
- Building footprints. Microsoft's US Building Footprints has 357,534 buildings in Delaware. The state file is a 13.5 MB zip and read in about 3 s. The files are at
https://minedbuildings.z5.web.core.windows.net/legacy/usbuildings-v2/<State>.geojson.zip; the olderusbuildingdata.blob.core.windows.netaddress now refuses public access.
Both are more recent than the 2020 census, so a few buildings will postdate the counts. That error is small compared with the one area weighting makes.
5. Mask with land cover in tobler
masked_area_interpolate turns the matching raster pixels into polygons, clips each source zone to them, then area-weights the clipped zones. Vectorising 10 m pixels is expensive: the Delaware window held 6.5 million built-up pixels. Resample to 30 m with a mode filter first:
import rasterio
from rasterio.enums import Resampling

with rasterio.open("worldcover_2021_delaware.tif") as src:
    h, w = src.height // 3, src.width // 3
    data = src.read(1, out_shape=(h, w), resampling=Resampling.mode)
    transform = src.transform * src.transform.scale(src.width / w, src.height / h)
    profile = src.profile | {"height": h, "width": w, "transform": transform, "nodata": 0}
with rasterio.open("worldcover_30m.tif", "w", **profile) as dst:
    dst.write(data, 1)
The 30 m raster had 689,463 built-up pixels, and the tobler call took about 10 s. Pass nodata=0 for WorldCover, because tobler's default is 255.
6. Weight by buildings
Buildings are closer to homes than a built-up pixel is: a built-up pixel can be a car park or a motorway junction. Use each building's representative point, count them in each source × target intersection, and share each source's people by those counts (Example 1; Example 3 scores every row):
ancillary weight                   people misallocated   median |error|
none (area weighting)            202,169  (20.4%)        34.6%
land only (water removed)        199,930  (20.2%)        33.4%
WorldCover built-up, 10 m        157,518  (15.9%)        25.8%
tobler mask, WorldCover 30 m     169,046  (17.1%)        28.5%
building count                   108,530  (11.0%)        16.7%
building footprint area          113,377  (11.5%)        18.6%
buildings of 40–400 m² only      121,355  (12.3%)        18.2%
7. Test a target that does not nest
Block groups sit inside tracts, which flatters every method. A 2 km grid does not nest. Scored against block populations assigned to cells by their representative points (Example 3):
2 km grid, 1,743 cells     misallocated     people put in cells that have nobody
area weighting          226,435 (22.9%)                               18,463
building count          117,920 (11.9%)                                3,041
The last column is what a map shows: area weighting paints population into fields, marsh and forest.
8. Keep the totals and a fallback
Every method above preserved the state total of 989,948. A source zone with no ancillary features at all, such as a tract that is all water or park, must fall back to area weighting. Otherwise its people vanish. Two Delaware block groups had no buildings; both were empty in the census too.
Redistributing Delaware's population with buildings
The data used on this page
Delaware's 2020 TIGER/Line blocks, which carry POP20; Microsoft's US Building Footprints for the state; and ESA WorldCover 2021 at 10 m, read from the two cloud-optimised tiles on AWS that cover Delaware and cropped to the state's bounding box.
import os

import geopandas as gpd
import rasterio
import requests
from rasterio.merge import merge

FILES = {
    "tl_2020_10_tabblock20.zip": "https://www2.census.gov/geo/tiger/TIGER2020/TABBLOCK20/tl_2020_10_tabblock20.zip",
    "Delaware.geojson.zip": "https://minedbuildings.z5.web.core.windows.net/legacy/usbuildings-v2/Delaware.geojson.zip",
}
for name, url in FILES.items():
    if not os.path.exists(name):
        r = requests.get(url, timeout=600)
        r.raise_for_status()
        open(name, "wb").write(r.content)

WC = "https://esa-worldcover.s3.eu-central-1.amazonaws.com/v200/2021/map/ESA_WorldCover_10m_2021_v200_{}_Map.tif"
if not os.path.exists("worldcover_2021_delaware.tif"):
    bounds = gpd.read_file("tl_2020_10_tabblock20.zip", columns=["GEOID20"]).to_crs(4326).total_bounds
    tiles = [rasterio.open("/vsicurl/" + WC.format(t)) for t in ("N36W078", "N39W078")]
    data, transform = merge(tiles, bounds=tuple(bounds))
    profile = tiles[0].profile | {"height": data.shape[1], "width": data.shape[2],
                                  "transform": transform, "compress": "deflate"}
    with rasterio.open("worldcover_2021_delaware.tif", "w", **profile) as dst:
        dst.write(data)
with rasterio.open("worldcover_2021_delaware.tif") as src:
    print(f"WorldCover window {src.width:,} x {src.height:,} pixels, "
          f"{(src.read(1) == 50).sum():,} built-up")
WorldCover window 9,658 x 16,661 pixels, 6,548,876 built-up
Example 1 — point-weighted dasymetric redistribution for any target zones
import numpy as np
import pandas as pd
import geopandas as gpd


def dasymetric(source, target, value, ancillary_points, weight=None, crs=5070):
    """Split source totals across target zones in proportion to ancillary points.

    Works for targets that do not nest in the sources: the allocation happens on
    the source x target intersections. Where a source has no ancillary points at
    all, it falls back to area weighting so nobody is dropped.
    """
    src = source[[value, "geometry"]].to_crs(crs).reset_index(names="src_id")
    tgt = target[["geometry"]].to_crs(crs).reset_index(names="tgt_id")
    pieces = gpd.overlay(src, tgt, how="intersection", keep_geom_type=True)
    pieces["area"] = pieces.area

    pts = ancillary_points.to_crs(crs)
    pts = pts.assign(_w=pts[weight] if weight else 1.0)[["_w", "geometry"]]
    hits = gpd.sjoin(pts, pieces[["geometry"]], predicate="within", how="inner")
    pieces["anc"] = hits.groupby("index_right")["_w"].sum().reindex(pieces.index).fillna(0)

    by_source = pieces.groupby("src_id")[["anc", "area"]].transform("sum")
    share = np.where(by_source["anc"] > 0, pieces["anc"] / by_source["anc"].where(by_source["anc"] > 0),
                     pieces["area"] / by_source["area"])
    pieces["estimate"] = pieces[value] * share
    out = pieces.groupby("tgt_id")["estimate"].sum()
    return out.reindex(tgt["tgt_id"]).fillna(0).set_axis(target.index)
buildings = gpd.read_file("/vsizip/Delaware.geojson.zip").to_crs(5070)
points = gpd.GeoDataFrame({"footprint": buildings.area},
geometry=buildings.representative_point(), crs=5070)
by_count = dasymetric(tracts, groups, "POP20", points)
by_area = dasymetric(tracts, groups, "POP20", points, weight="footprint")Example 2 — counting land-cover classes per zone without vectorising pixels
import rasterio
from rasterio.features import rasterize


def raster_class_counts(zones, raster_path, classes):
    """Count pixels of the given classes inside each zone (zones in any CRS)."""
    with rasterio.open(raster_path) as src:
        data = src.read(1)
        shapes = zones.to_crs(src.crs).geometry
        ids = rasterize(((geom, i + 1) for i, geom in enumerate(shapes)),
                        out_shape=data.shape, transform=src.transform,
                        fill=0, dtype="uint32")
    mask = np.isin(data, classes)
    counts = np.bincount(ids[mask], minlength=len(zones) + 1)[1:]
    return pd.Series(counts, index=zones.index)
Burning the 706 block groups into the 16,661 × 9,658 pixel window and counting built-up pixels took 1.5 s, against about 10 s for tobler's vectorising route on a raster with a ninth as many pixels. For zones that nest in the sources, the counts become weights directly. For non-nesting zones, pass source × target intersections as zones. Each rasterised zone keeps the pixels whose centres fall inside it, so very small pieces can receive none.
Example 3 — scoring a redistribution
def score(estimate, truth):
    """Error of a redistribution against known target totals."""
    error = estimate.reindex(truth.index).fillna(0) - truth
    pct = error.abs() / truth.where(truth > 0) * 100
    return {
        "total": round(float(estimate.sum())),
        "misallocated": round(float(error.abs().sum() / 2)),
        "misallocated_pct": round(float(error.abs().sum() / 2 / truth.sum() * 100), 1),
        "median_abs_pct": round(float(pct.median()), 1),
    }


for name, est in [("area-weighted", aw["POP20"].set_axis(groups.index)), ("buildings (count)", by_count)]:
    print(f"{name:20} {score(est, truth)}")
area-weighted {'total': 989948, 'misallocated': 202169, 'misallocated_pct': 20.4, 'median_abs_pct': 34.6}
buildings (count) {'total': 989948, 'misallocated': 108530, 'misallocated_pct': 11.0, 'median_abs_pct': 16.7}
"Misallocated" is half the sum of absolute errors. Each misplaced person appears once as a surplus and once as a deficit.
Example 4 — score every method on the same test
Land only uses the blocks with some land (ALAND20 > 0) as the weight; WorldCover 10 m counts built-up pixels per block group with raster_class_counts.
import time
from shapely.geometry import box
from tobler.area_weighted import area_interpolate
from tobler.dasymetric import masked_area_interpolate


def score_line(estimate, truth):
    """People in the wrong zone (half the absolute error) and the median zone's error."""
    err = estimate.reindex(truth.index).fillna(0) - truth
    wrong = err.abs().sum() / 2
    return f"{wrong:>10,.0f}  ({wrong / truth.sum():5.1%}) {(err.abs() / truth.where(truth > 0)).median():>12.1%}"


def nested_share(counts):
    """Share each tract's people among its block groups by a per-group weight."""
    tract_of = counts.index.str[:11]
    total = counts.groupby(tract_of).transform("sum")
    return (tracts["POP20"].reindex(tract_of).to_numpy() * counts / total.where(total > 0)).fillna(0)


t = time.perf_counter()
blocks_all = gpd.read_file("tl_2020_10_tabblock20.zip", columns=["GEOID20", "POP20", "ALAND20"])
tracts = blocks_all.dissolve(by=blocks_all.GEOID20.str[:11], aggfunc={"POP20": "sum"})
groups = blocks_all.dissolve(by=blocks_all.GEOID20.str[:12], aggfunc={"POP20": "sum"})
truth = groups["POP20"]
print(f"dissolve: {time.perf_counter() - t:.1f} s; {len(tracts)} tracts, {len(groups)} block groups")

t = time.perf_counter()
aw = area_interpolate(tracts.to_crs(5070), groups.to_crs(5070), extensive_variables=["POP20"])["POP20"]
aw.index = groups.index
print(f"area weighting: {time.perf_counter() - t:.2f} s")

land = blocks_all[blocks_all.ALAND20 > 0]
land_groups = land.dissolve(by=land.GEOID20.str[:12]).to_crs(5070)
by_land = nested_share(land_groups.area.reindex(groups.index).fillna(0))

t = time.perf_counter()
by_wc10 = nested_share(raster_class_counts(groups, "worldcover_2021_delaware.tif", [50]))
print(f"raster_class_counts on the 10 m window: {time.perf_counter() - t:.1f} s")

with rasterio.open("worldcover_2021_delaware.tif") as src:
    h, w = src.height // 3, src.width // 3
    data = src.read(1, out_shape=(h, w), resampling=Resampling.mode)
    transform = src.transform * src.transform.scale(src.width / w, src.height / h)
    profile = src.profile | {"height": h, "width": w, "transform": transform, "nodata": 0}
with rasterio.open("worldcover_30m.tif", "w", **profile) as dst:
    dst.write(data, 1)
t = time.perf_counter()
mask = masked_area_interpolate(tracts.to_crs(5070), groups.to_crs(5070), raster="worldcover_30m.tif",
                               pixel_values=[50], extensive_variables=["POP20"], nodata=0)["POP20"]
mask.index = groups.index
print(f"30 m raster: {(data == 50).sum():,} built-up pixels; tobler mask: {time.perf_counter() - t:.1f} s, "
      f"total {mask.sum():,.0f}")

t = time.perf_counter()
buildings = gpd.read_file("/vsizip/Delaware.geojson.zip").to_crs(5070)
print(f"{len(buildings):,} buildings read in {time.perf_counter() - t:.1f} s")
points = gpd.GeoDataFrame({"footprint": buildings.area},
                          geometry=buildings.representative_point(), crs=5070)
t = time.perf_counter()
by_count = dasymetric(tracts, groups, "POP20", points)
print(f"dasymetric(): {time.perf_counter() - t:.1f} s")
by_area = dasymetric(tracts, groups, "POP20", points, weight="footprint")
homes = points[points.footprint.between(40, 400)]
by_homes = dasymetric(tracts, groups, "POP20", homes)

print(f"{'ancillary weight':30}{'people misallocated':>24}{'median |error|':>17}")
for name, est in [("none (area weighting)", aw), ("land only (water removed)", by_land),
                  ("WorldCover built-up, 10 m", by_wc10), ("tobler mask, WorldCover 30 m", mask),
                  ("building count", by_count), ("building footprint area", by_area),
                  ("buildings of 40–400 m² only", by_homes)]:
    print(f"{name:30}{score_line(est, truth)}  total {est.sum():,.0f}")
with_buildings = gpd.sjoin(points, groups.to_crs(5070)[["geometry"]].reset_index(), predicate="within")["GEOID20"]
empty = groups.index.difference(with_buildings.unique())
print("block groups with no buildings:", len(empty), "census population there:", int(truth[empty].sum()))
print(f"{len(points) - len(with_buildings):,} footprints fall outside every block group")
worst = (aw - truth).abs().idxmax()
print(f"worst block group {worst}: counted {truth[worst]:,}, area weighting {aw[worst]:,.0f}, buildings {by_count[worst]:,.0f}")
native = area_interpolate(tracts, groups, extensive_variables=["POP20"])["POP20"].set_axis(groups.index)
print(f"same interpolation in {tracts.crs.to_string()}: largest change {(native - aw).abs().max():.1f} people")

# a 2 km grid, which does not nest
g = groups.to_crs(5070)
xmin, ymin, xmax, ymax = g.total_bounds
cells = gpd.GeoDataFrame(geometry=[box(x, y, x + 2000, y + 2000) for x in np.arange(xmin, xmax, 2000)
                                   for y in np.arange(ymin, ymax, 2000)], crs=5070)
cells = cells[cells.intersects(g.union_all())].reset_index(drop=True)
bp = blocks_all.to_crs(5070)
bp["geometry"] = bp.representative_point()
cell_truth = gpd.sjoin(bp, cells, predicate="within").groupby("index_right")["POP20"].sum().reindex(cells.index).fillna(0)
grid_aw = area_interpolate(tracts.to_crs(5070), cells, extensive_variables=["POP20"])["POP20"]
grid_bc = dasymetric(tracts, cells, "POP20", points)
print(f"2 km grid, {len(cells):,} cells")
for name, est in [("area weighting", grid_aw), ("building count", grid_bc)]:
    err = est - cell_truth
    print(f"{name:16}{err.abs().sum() / 2:>10,.0f} ({err.abs().sum() / 2 / cell_truth.sum():.1%})  "
          f"in empty cells {est[cell_truth == 0].sum():>8,.0f}")
dissolve: 3.4 s; 262 tracts, 706 block groups
area weighting: 0.55 s
raster_class_counts on the 10 m window: 1.5 s
30 m raster: 689,463 built-up pixels; tobler mask: 10.3 s, total 989,948
357,534 buildings read in 3.3 s
dasymetric(): 1.1 s
ancillary weight people misallocated median |error|
none (area weighting) 202,169 (20.4%) 34.6% total 989,948
land only (water removed) 199,930 (20.2%) 33.4% total 989,948
WorldCover built-up, 10 m 157,518 (15.9%) 25.8% total 989,948
tobler mask, WorldCover 30 m 169,046 (17.1%) 28.5% total 989,948
building count 108,530 (11.0%) 16.7% total 989,948
building footprint area 113,377 (11.5%) 18.6% total 989,948
buildings of 40–400 m² only 121,355 (12.3%) 18.2% total 989,948
block groups with no buildings: 2 census population there: 0
8,539 footprints fall outside every block group
worst block group 100030145021: counted 2,312, area weighting 5,977, buildings 4,536
same interpolation in EPSG:4269: largest change 2.8 people
2 km grid, 1,743 cells
area weighting 226,435 (22.9%) in empty cells 18,463
building count 117,920 (11.9%) in empty cells 3,041
Why buildings beat land cover
Why area weighting fails inside a single tract
A tract is drawn to hold about 4,000 people, not to be uniform. On its edge, a suburban tract may include a subdivision, a golf course and farmland. Area weighting gives the farmland its share of the subdivision's residents.
The worst Delaware block group, 100030145021, has 2,312 residents. Area weighting gave it 5,977 because it holds a large share of its tract's land. The building-weighted estimate was 4,536: still wrong, but by 2,224 people rather than 3,665.
Why removing water barely helped
Water masking is the textbook first step, and here it moved the error from 20.4% to 20.2%. Delaware's water is concentrated in a few coastal and bay tracts. Inside a typical tract, the people are unevenly spread over dry land. A mask only helps if it removes the area where people are not, and on land that means knowing where the buildings are.
Why buildings beat land cover
The built-up class marks impervious surface, and impervious surface includes car parks, industrial estates and roads. It improved on area weighting (15.9%) but still spread residents over commercial land.
Building counts come closer to dwellings. Counting buildings (11.0%) beat weighting by footprint area (11.5%). A warehouse's large footprint would otherwise attract the people who live in the houses nearby. Keeping only buildings of 40–400 m² made things worse (12.3%). The filter discards terraces and apartment blocks mapped as single large polygons, which are exactly where people are densest.
Why the grid result matters more than the block group result
Targets that nest inside the sources limit how wrong any method can be, because each source's people stay inside it. A grid cuts across tracts, and there area weighting put 18,463 people in cells where the census counted none. On a population grid, those phantom residents are the first thing a reader notices.
What the remaining 11% is
Buildings are a proxy. Garages, sheds, barns, shops and schools are counted as if they were homes. Vacant homes are counted as occupied. The footprints are from years after the 2020 census. Better proxies include residential address points, building type attributes and housing unit counts, and each of those would reduce the error further. Measure before assuming any of them does.
Projection, nodata defaults and raster size
- Project before measuring area. tobler warns "Geometry is in a geographic CRS" if you pass EPSG:4269 zones; the result here moved by at most 2.8 people, but do not rely on that elsewhere.
- tobler's
nodatadefaults to 255. WorldCover uses 0; pass it explicitly. - Resample large rasters before
masked_area_interpolate. It vectorises every matching pixel before overlaying. - WorldCover is in EPSG:4326. Pixel area varies with latitude by about 2% across a state the size of Delaware; for a continent, weight by pixel area.
- Use representative points, not centroids, for footprints. A centroid of an L-shaped building can fall in the neighbouring zone.
- 8,539 Delaware footprints fell outside every block group, mostly beyond the census coastline; they cannot receive people and should not.
- Fallback is required. A source zone with no ancillary features must keep its people somewhere.
- Intensive variables do not redistribute. tobler's
intensive_variablesaverages them; it does not make a median meaningful on a new zone.
Internal links
- How to interpolate to polygons instead of a grid — area weighting, the baseline this guide beats
- How to compare census years across changed boundaries — the exact method when blocks exist
- How to calculate population-weighted centroids — the same block counts, used for location
- Fixing census totals that do not add up after aggregation — why a preserved total proves little
- How to count the population within reach of each facility — a common consumer of redistributed population
- How to calculate zonal statistics in Python — raster counts per polygon
- How to perform a spatial join in Python — the point-in-polygon step in Example 1
- The modifiable areal unit problem explained — why the zones change the answer
- How to count buildings and people exposed to a hazard zone — dasymetric weighting against a hazard footprint
FAQ
What is dasymetric mapping?
Redistributing a count from source zones to other zones using ancillary data about where the count can occur, such as buildings or built-up land. It is area weighting restricted to the places people actually live.
How much better than area weighting is it?
On Delaware tracts redistributed to block groups, area weighting misallocated 20.4% of the population, a WorldCover built-up mask 15.9% and building counts 11.0%. On a 2 km grid, buildings halved the error, from 22.9% to 11.9%.
Which Python function does it?
tobler.dasymetric.masked_area_interpolate takes a raster and the pixel values to keep. For vector ancillary data such as building footprints, weight the source × target intersections yourself, as in Example 1.
Is removing water enough?
Not in this test: it improved the error from 20.4% to 20.2%. The unevenness that matters is on land, between built and unbuilt areas.
Should I weight by building count or footprint area?
Count did slightly better here (11.0% against 11.5%), because large non-residential footprints attract people under area weighting. Filtering to small buildings made it worse.
How do I know it worked on my data?
Score it where the truth is known. Dissolve census blocks into two levels, redistribute from the upper to the lower, and compare against the block totals before trusting the method on zones where you cannot check.