
How to Measure Bank Deposit Market Share by County
On this page
Problem statement
How concentrated is banking in a county? Regulators answer with deposit market shares and the Herfindahl-Hirschman Index (HHI), the sum of the squared percentage shares of every bank, from near 0 for a market of many equal banks to 10,000 for a single bank. It is the measure used when the Federal Reserve and the Justice Department review a bank merger, and the Summary of Deposits is its source. Computed naively it is wrong in the counties where banks book national deposits at their head offices. This page computes the HHI for every county from branch deposits, shows how many banks it takes to lower it, and how much head offices distort it.
Quick answer
Sum deposits by county and bank over branches, leaving out main offices, and square the shares:
branch = sod[sod.BRNUM != 0]                                # main offices hold deposits booked from everywhere
share = branch.groupby(["STCNTYBR", "CERT"]).deposits.sum()
share = share / share.groupby(level=0).transform("sum")
hhi = (share.mul(100) ** 2).groupby(level=0).sum()
top = share.groupby(level=0).max()
print(f"counties: {len(hhi):,}; median HHI {hhi.median():,.0f}; one bank holds over half the deposits in {(top > 0.5).sum():,} counties")
counties: 3,159; median HHI 2,868; one bank holds over half the deposits in 1,134 counties
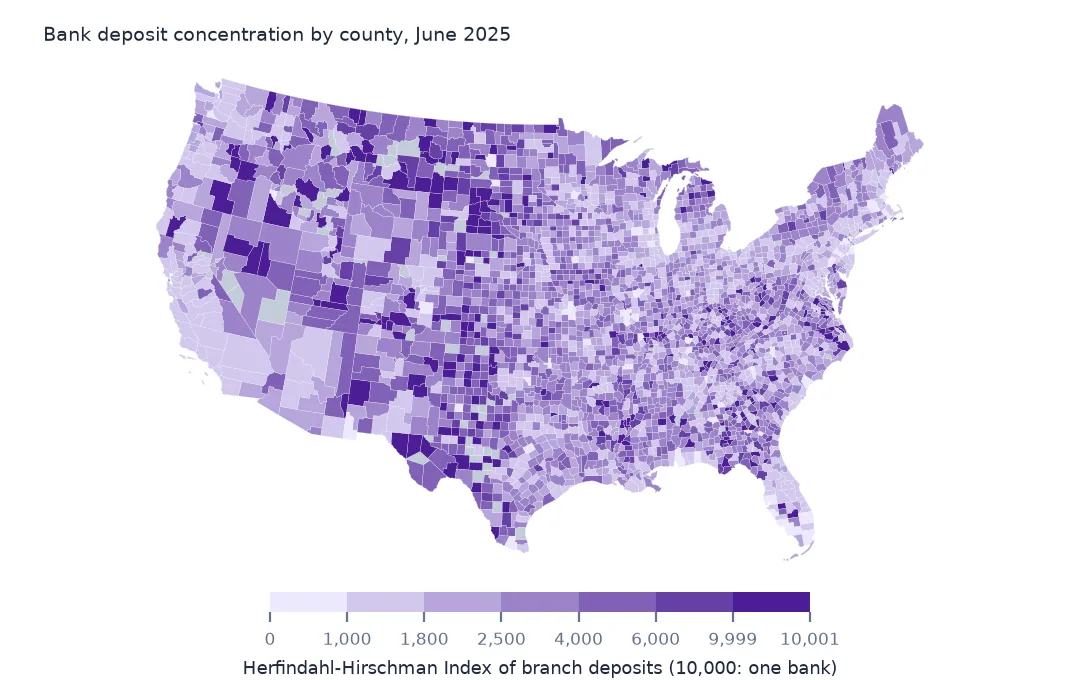
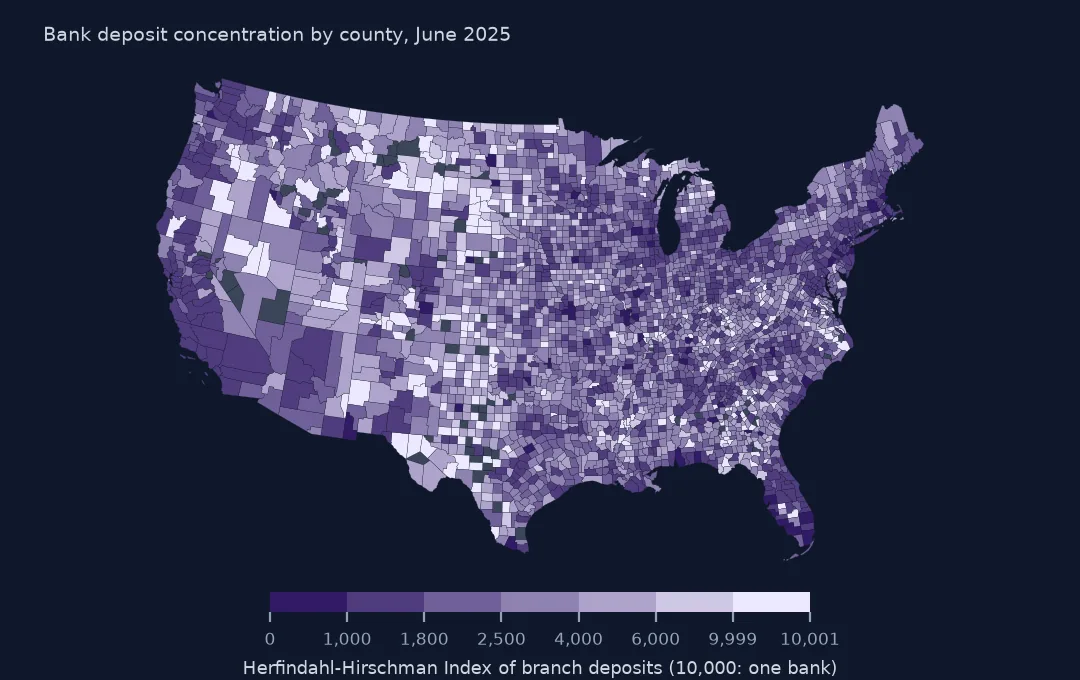
Across 3,159 counties the median HHI is 2,868, which by merger-review standards is a concentrated market. In 1,134 counties, more than a third, one bank holds over half of all branch deposits. Local banking is far more concentrated than national banking, because most counties are served by a handful of banks.
What HHI says, and what distorts it
1. What HHI measures
n = branch.groupby("STCNTYBR").CERT.nunique()
print(pd.DataFrame({"banks": n, "hhi": hhi}).groupby(pd.cut(n, [0, 1, 2, 5, 10, 500])).hhi.agg(["size", "median"]).round(0).to_string())
size median
CERT
(0, 1] 287 10000.0
(1, 2] 385 5510.0
(2, 5] 982 3510.0
(5, 10] 861 2149.0
(10, 500] 644 1422.0
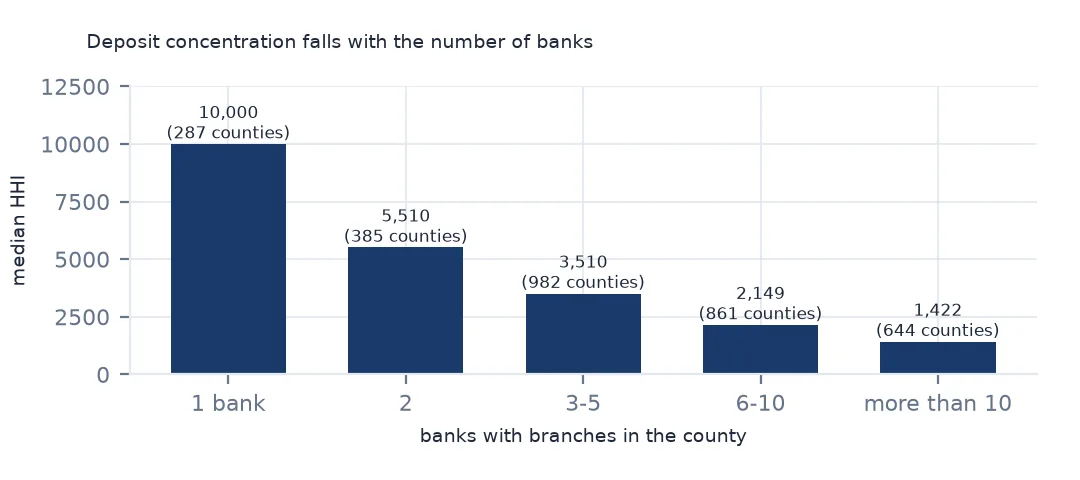
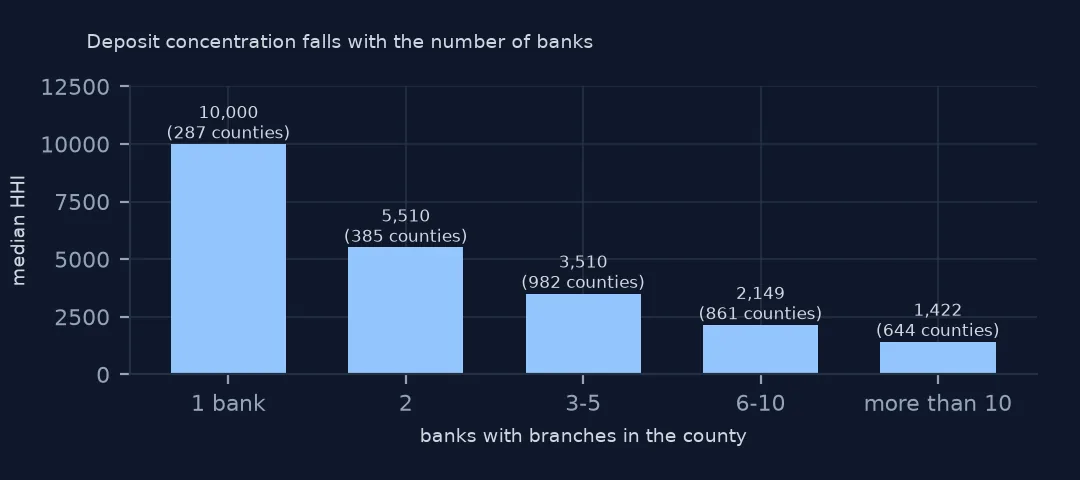
The index follows the number of banks closely. The 287 counties with a single bank score 10,000 by definition; with two banks the median is 5,510, with three to five 3,510, with six to ten 2,149, and only counties with more than ten banks have a median near the 1,422 of the most competitive group. HHI is a count of competitors in disguise, weighted by how evenly they share the market.
2. Why main offices are left out
with_main = sod.groupby(["STCNTYBR", "CERT"]).deposits.sum()
hhi_main = ((with_main / with_main.groupby(level=0).transform("sum")).mul(100) ** 2).groupby(level=0).sum()
d = (hhi_main - hhi.reindex(hhi_main.index)).dropna()
print(f"counties where including main offices raises HHI by over 1,000: {(d > 1000).sum()}")
print(pd.DataFrame({"with_main": hhi_main, "branches_only": hhi}).loc[["39049", "10003", "46099"]].round(0).to_string())
counties where including main offices raises HHI by over 1,000: 209
with_main branches_only
STCNTYBR
39049 2965.0 1969.0
10003 4277.0 8288.0
46099 9107.0 9678.0
Including main offices raises the HHI by more than 1,000 points in 209 counties. In some counties it lowers it instead: New Castle County, Delaware, home of Wilmington, scores 8,288 on branches but 4,277 with main offices included, because several banks book large deposits at head offices there. Minnehaha County, South Dakota, home of Sioux Falls, scores 9,107 and 9,678. Leaving main offices out is a rough fix; a branch that books national deposits, as JPMorgan's Manhattan office does, still distorts its county.
3. The largest markets
dep = branch.groupby("STCNTYBR").deposits.sum()
big = dep.nlargest(8).index
print(pd.DataFrame({"deposits_bn": dep[big] / 1e9, "hhi": hhi[big], "banks": n[big]}).round(0).to_string())
deposits_bn hhi banks
STCNTYBR
36061 1194.0 4659.0 59
06037 463.0 1145.0 87
46099 351.0 9678.0 25
10003 301.0 8288.0 17
06075 285.0 4599.0 42
48201 282.0 3635.0 76
48113 255.0 2868.0 105
17031 255.0 1632.0 77
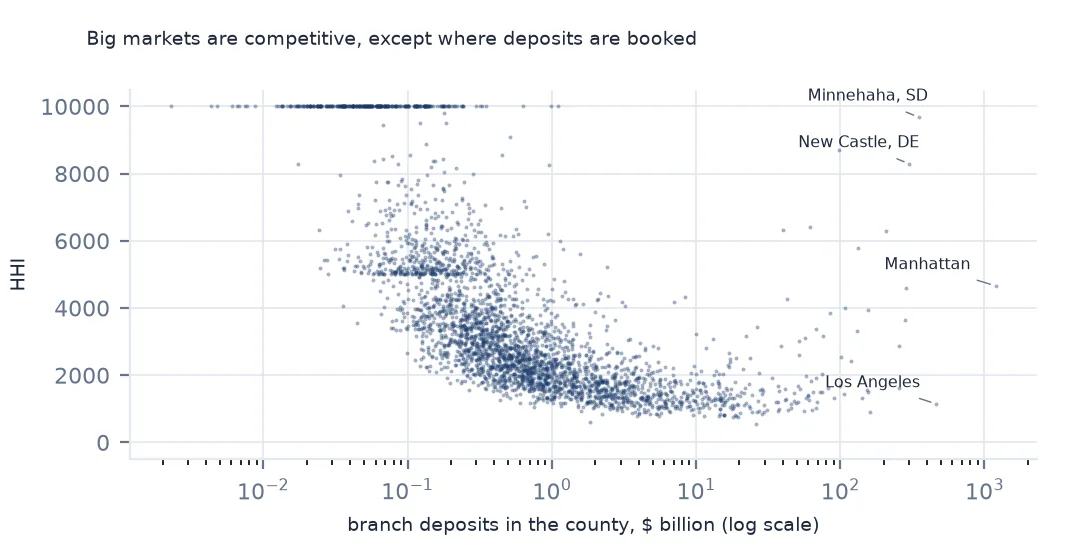
The largest deposit markets show the problem. New York County, Manhattan, has $1,194 billion in branches and an HHI of 4,659 despite 59 banks, because one JPMorgan branch holds more than half of it. Los Angeles County, with 87 banks and $463 billion, scores 1,145, the competitive market its size suggests. Minnehaha and New Castle counties rank third and fourth by deposits with HHIs of 9,678 and 8,288: their deposits are national accounts booked at a few offices in Sioux Falls and Wilmington.
Concentration and county size
The data used on this page
The FDIC's Summary of Deposits for 2015 and 2025, every office of every FDIC-insured institution with its deposits as of 30 June, from the BankFind Suite API, downloaded on 28 October 2026 and saved on this site, because banks amend past reports and the API serves the revised figures. Public domain. Deposits are reported in thousands of dollars.
from pathlib import Path
import zipfile

import geopandas as gpd
import numpy as np
import pandas as pd
import requests

Path("data").mkdir(exist_ok=True)
# FDIC Summary of Deposits for 2015 and 2025 (every branch, deposits as of 30 June) from the BankFind Suite API, with
# the Census Bureau's 2024 county population estimates, 2020 tract centres of population, counties and states.
# Saved 28 October 2026: the API serves revised years as banks amend their reports.
# Live: https://api.fdic.gov/banks/sod?filters=YEAR:2025&limit=10000&offset=0
ARCHIVE = "fdic-sod-2026-10-28.zip"
if not Path(f"data/{ARCHIVE}").exists():
    Path(f"data/{ARCHIVE}").write_bytes(requests.get(f"https://data.spatialworkflow.io/{ARCHIVE}", timeout=600).content)
Z = zipfile.ZipFile(f"data/{ARCHIVE}")
for f in ["cb_2024_us_county_20m.zip", "cb_2024_us_state_20m.zip"]:
    Path(f"data/{f}").write_bytes(Z.read(f))
def read_sod(year):
    d = pd.read_csv(Z.open(f"fdic-sod-{year}.csv"), dtype={"ZIPBR": str})
    d["STCNTYBR"] = d.STCNTYBR.astype(str).str.zfill(5)          # county FIPS, stored as a number
    d["deposits"] = d.DEPSUMBR * 1000                              # reported in thousands of dollars
    return d
sod = read_sod(2025)
print(f"FDIC Summary of Deposits 2025: {len(sod):,} offices, ${sod.deposits.sum() / 1e12:,.2f} trillion in deposits")
FDIC Summary of Deposits 2025: 76,097 offices, $18.10 trillion in deposits
Example 1: concentration and county size
from scipy.stats import spearmanr
r = spearmanr(dep.reindex(hhi.index), hhi)
print(f"rank correlation of deposits with HHI: {r.statistic:.2f}")
print(f"counties with one bank only: {(n == 1).sum()}")
rank correlation of deposits with HHI: -0.81
counties with one bank only: 287
Across counties, the rank correlation between total deposits and HHI is -0.81: big markets are competitive, small ones concentrated, as expected. The 287 single-bank counties are almost all small rural ones. Where the relationship breaks, as in Manhattan, Sioux Falls and Wilmington, the deposits are not local.
Internal links
- Deposits booked at head offices — the distortion removed here
- The largest banks — national concentration
- Branches per resident — the other side of local banking
- Reading the survey — the deposit column